Generative Engine Optimization Posts
How Can GEO for Startups Build AI Search Visibility on a Budget?
Startups face a different AI search problem from established companies. They need visibility while building the product, refining positioning, and managing limited marketing resources. A large GEO program can therefore consume budget before the company knows which discovery gaps deserve serious investment. GEO for startups should begin with ruthless prioritization. A young company needs enough public information for buyers and AI systems to understand its category, product, audience, expertise, and proof. It does not need hundreds of optimized pages or an expensive monitoring stack from the first month. The strongest early approach is to build a small information system around real commercial questions. Startups can then expand after evidence shows where AI-led discovery is influencing their market. Key Takeaways GEO for startups should begin with commercial clarity before expanding content production. Startups need strong core pages before funding large informational content libraries. Commercial buyer questions deserve priority over broad prompts with weak business relevance. Founder expertise can build authority without creating another expensive publishing operation separately. Existing pages should be improved before startups commission large volumes of content. Free first-party measurement can establish visibility baselines before paid tools become necessary. Startups should delay advanced GEO work until basic search foundations remain reliable. More GEO spending should follow evidence of opportunity rather than market excitement. What Does GEO for Startups Mean When the Budget Is Limited? GEO for startups improves how a young company is understood and surfaced during AI-assisted research without treating every possible visibility tactic as urgent. The work should focus first on commercial pages, buyer questions, credible proof, founder expertise, and simple measurement. Broader content investment can follow these foundations to produce useful learning. The wider principles behind Generative Engine Optimization still apply. Startups need useful content, clear entity information, and credible public evidence. Their smaller budget changes the sequence rather than the basic requirement. The shift is already visible in how people search. Deloitte predicts that 29% of adults in developed markets will use AI-enhanced search daily during 2026. That makes AI-assisted discovery part of routine search behavior rather than a separate experimental channel. The better starting point is understanding which information buyers need before they can confidently consider the company. Why GEO for Startups Is a Sequencing Problem? Limited budgets make sequencing more important than volume. A startup can spend heavily on AI visibility tools or new blogs while its positioning remains unclear. GEO for startups works better when each investment removes the next obstacle stopping buyers and AI systems from understanding, validating, or considering the company. The difference becomes clearer when activities are separated by timing. Spend Now Why It Deserves Priority Delay Until Clear product or service pages Buyers need accurate category and value information first Core positioning becomes stable Commercial question research Reveals which information can influence buyer consideration Priority journeys are already mapped Existing-page improvements Builds on assets already available to search systems Important pages are already strong Founder expertise content Adds credible public expertise around emerging brands Founder has no differentiated insight Basic visibility measurement Creates evidence before larger investments begin A baseline already exists Large prompt-monitoring platforms Useful after the prompt portfolio becomes meaningful Recurring tracking needs justify cost This sequence also fits Google’s current guidance. Google states that AI Overviews and AI Mode need no special technical optimization beyond normal Search eligibility. Strong SEO fundamentals and useful content remain the foundation. Startups can therefore avoid paying early for technical tactics presented as mandatory “AI hacks.” What Is the Minimum Viable GEO System for a Startup? A minimum viable GEO system for startups contains the smallest set of assets needed to accurately describe the startup and support relevant buyer research. It should cover category positioning, commercial questions, product proof, founder expertise, and repeatable visibility checks. Everything else should earn its place after this system works. Clear Commercial Information Layer: The homepage and core product pages should explain what the startup provides and who should consider it. Buyers should understand the problem being solved and the major use cases without having to interpret vague category language or conflicting descriptions across the website. Commercial Prompt Map: Start with 20–30 questions buyers may ask before contacting the company. Include category discovery and product-fit questions alongside comparisons or objections. Our GEO audit checklist explains why commercial prompts should define the audit before teams examine broad visibility metrics. Enough Proof to Support Important Claims: Case evidence, customer outcomes, founder experience, technical documentation, or original insights should support the company’s strongest claims. A startup with limited brand recognition needs verifiable information because buyers cannot rely on years of established market reputation. Small Supporting Content Library: Publish content only where important buyer questions lack a suitable answer. The AI content gap analysis framework helps startups separate genuine information gaps from topics that already have adequate coverage on existing pages. Repeatable Baseline: Record whether the startup appears across selected commercial prompts and which sources support relevant answers. A simple spreadsheet can establish the first benchmark without purchasing another platform before the team knows what deserves recurring measurement. Which Startup Pages Should You Fix Before Publishing More Content? Startups should improve pages closest to commercial evaluation before expanding their blog library. Buyers and AI systems first need accurate information about the company, product, audience, use cases, proof, and commercial model. Missing details on these pages create larger problems with GEO for startups than an incomplete top-of-funnel publishing calendar. Review pages in this order: Page Question It Must Answer Common Startup Gap Homepage What does this company actually do? Vague category or outcome language Product or service page How does the solution work? Feature claims without enough explanation Use-case page Does this fit my problem? Generic scenarios without buyer context Pricing page How does the commercial model work? Important buying conditions remain unclear Case study Has this worked before? Testimonials without enough supporting detail Founder page Why trust this company’s expertise? Founder experience remains disconnected from category SaaS startups can go
Startups face a different AI search problem from established companies. They need visibility while building the product, refining positioning, and managing limited marketing resources. A large GEO program can therefore consume budget before the company knows which discovery gaps deserve serious investment. GEO for startups should begin with ruthless prioritization. A young company needs enough public information for buyers and AI systems to understand its category, product, audience, expertise, and proof. It does not need hundreds of optimized pages or an expensive monitoring stack from the first month. The strongest early approach is to build a small information system around real commercial questions. Startups can then expand after evidence shows where AI-led discovery is influencing their market. Key Takeaways GEO for startups should begin with commercial clarity before expanding content production. Startups need strong core pages before funding large informational content libraries. Commercial buyer questions deserve priority over broad prompts with weak business relevance. Founder expertise can build authority without creating another expensive publishing operation separately. Existing pages should be improved before startups commission large volumes of content. Free first-party measurement can establish visibility baselines before paid tools become necessary. Startups should delay advanced GEO work until basic search foundations remain reliable. More GEO spending should follow evidence of opportunity rather than market excitement. What Does GEO for Startups Mean When the Budget Is Limited? GEO for startups improves how a young company is understood and surfaced during AI-assisted research without treating every possible visibility tactic as urgent. The work should focus first on commercial pages, buyer questions, credible proof, founder expertise, and simple measurement. Broader content investment can follow these foundations to produce useful learning. The wider principles behind Generative Engine Optimization still apply. Startups need useful content, clear entity information, and credible public evidence. Their smaller budget changes the sequence rather than the basic requirement. The shift is already visible in how people search. Deloitte predicts that 29% of adults in developed markets will use AI-enhanced search daily during 2026. That makes AI-assisted discovery part of routine search behavior rather than a separate experimental channel. The better starting point is understanding which information buyers need before they can confidently consider the company. Why GEO for Startups Is a Sequencing Problem? Limited budgets make sequencing more important than volume. A startup can spend heavily on AI visibility tools or new blogs while its positioning remains unclear. GEO for startups works better when each investment removes the next obstacle stopping buyers and AI systems from understanding, validating, or considering the company. The difference becomes clearer when activities are separated by timing. Spend Now Why It Deserves Priority Delay Until Clear product or service pages Buyers need accurate category and value information first Core positioning becomes stable Commercial question research Reveals which information can influence buyer consideration Priority journeys are already mapped Existing-page improvements Builds on assets already available to search systems Important pages are already strong Founder expertise content Adds credible public expertise around emerging brands Founder has no differentiated insight Basic visibility measurement Creates evidence before larger investments begin A baseline already exists Large prompt-monitoring platforms Useful after the prompt portfolio becomes meaningful Recurring tracking needs justify cost This sequence also fits Google’s current guidance. Google states that AI Overviews and AI Mode need no special technical optimization beyond normal Search eligibility. Strong SEO fundamentals and useful content remain the foundation. Startups can therefore avoid paying early for technical tactics presented as mandatory “AI hacks.” What Is the Minimum Viable GEO System for a Startup? A minimum viable GEO system for startups contains the smallest set of assets needed to accurately describe the startup and support relevant buyer research. It should cover category positioning, commercial questions, product proof, founder expertise, and repeatable visibility checks. Everything else should earn its place after this system works. Clear Commercial Information Layer: The homepage and core product pages should explain what the startup provides and who should consider it. Buyers should understand the problem being solved and the major use cases without having to interpret vague category language or conflicting descriptions across the website. Commercial Prompt Map: Start with 20–30 questions buyers may ask before contacting the company. Include category discovery and product-fit questions alongside comparisons or objections. Our GEO audit checklist explains why commercial prompts should define the audit before teams examine broad visibility metrics. Enough Proof to Support Important Claims: Case evidence, customer outcomes, founder experience, technical documentation, or original insights should support the company’s strongest claims. A startup with limited brand recognition needs verifiable information because buyers cannot rely on years of established market reputation. Small Supporting Content Library: Publish content only where important buyer questions lack a suitable answer. The AI content gap analysis framework helps startups separate genuine information gaps from topics that already have adequate coverage on existing pages. Repeatable Baseline: Record whether the startup appears across selected commercial prompts and which sources support relevant answers. A simple spreadsheet can establish the first benchmark without purchasing another platform before the team knows what deserves recurring measurement. Which Startup Pages Should You Fix Before Publishing More Content? Startups should improve pages closest to commercial evaluation before expanding their blog library. Buyers and AI systems first need accurate information about the company, product, audience, use cases, proof, and commercial model. Missing details on these pages create larger problems with GEO for startups than an incomplete top-of-funnel publishing calendar. Review pages in this order: Page Question It Must Answer Common Startup Gap Homepage What does this company actually do? Vague category or outcome language Product or service page How does the solution work? Feature claims without enough explanation Use-case page Does this fit my problem? Generic scenarios without buyer context Pricing page How does the commercial model work? Important buying conditions remain unclear Case study Has this worked before? Testimonials without enough supporting detail Founder page Why trust this company’s expertise? Founder experience remains disconnected from category SaaS startups can go
How Can GEO for Ecommerce Help Products Get Recommended in AI Search?
A shopper can now ask for lightweight running shoes under ₹8,000 for wide feet and hot weather. AI shopping can narrow hundreds of options before the shopper reaches an ecommerce website. This changes which products enter consideration before any retailer receives a visit. This shift changes GEO for ecommerce. Brands must provide AI systems with sufficiently reliable information to identify and compare products. They must also explain their fit for the shopping situation. Category rankings still matter, yet they no longer cover the complete discovery journey. NIQ found that 42% of consumers had used an AI tool for shopping during the previous month in May 2026. AI is entering product decisions before many retailers have adapted their content systems. Early product understanding is already a practical visibility problem. This blog will help you understand how GEO for ecommerce helps brands improve their AI citations. Key Takeaways GEO for ecommerce improves product understanding before AI systems build shortlists for shoppers. Strong product feeds establish facts while editorial content explains real buying fit. AI shopping prompts combine needs, budgets, preferences, constraints, and product trade-offs. Product pages need decision context instead of repeating specifications or promotional claims. Reviews help AI systems assess real usage beyond retailer-controlled product descriptions online. Large catalogs should prioritize recommendation opportunities rather than optimizing every SKU equally. Google Merchant Center now reports AI shopping visibility for eligible Indian merchants. Ecommerce GEO succeeds when recommendation visibility connects with qualified visits and revenue. How Has AI Shopping Changed What Ecommerce Brands Need to Optimize? AI shopping has shifted product discovery from keyword matching toward constraint matching. Shoppers can describe price limits, intended use, preferences, dimensions, performance needs, and known concerns in a single prompt. Brands must therefore optimize the information needed to narrow options, rather than focusing only on individual category keywords. Google supports conversational shopping across AI Mode and Gemini in India. Its systems combine listings with prices, reviews, inventory information, and product-specific comparisons. The Shopping Graph contained over 60 billion listings by May 2026. Shoppers can therefore compare products across an enormous catalog. ChatGPT follows a similar path. OpenAI says shoppers can refine their choices based on budget, preferences, and constraints, then compare suitable options side by side. Product discovery can use merchant feeds through the Agentic Commerce Protocol alongside public retail information. Our AI search trends analysis explains this broader move toward AI-led shortlisting. Ecommerce brands experience it most directly because generated recommendations can decide which products earn further consideration before shoppers search for a specific retailer or brand. What Features Does GEO for Ecommerce Optimize? GEO for ecommerce improves the information environment surrounding a product so AI systems can understand when it fits a shopper’s request. It connects current product data with useful page content, supporting buying information, external evidence, and measurement. Each layer solves a different problem within the recommendation process. This is broader than a schema project or another product description rewrite. The broader discipline of Generative Engine Optimization explains how brands become understandable across generative discovery. Ecommerce introduces rapidly changing commercial facts and purchase-specific evidence, so AI systems need more than editorial authority as product details change. Our guide to GEO services provides the wider context for this source ecosystem. Product discovery adds another layer because merchant feeds, product pages, reviews, buying guides, and external sources can all shape how a product is identified, compared, or recommended. Recommendation Question Information Needed Best Source Is the product available? Identity, price, stock, seller information Feed and product page Does it match the request? Attributes, size, compatibility, intended use Product data and copy Which option fits better? Differences, trade-offs, suitability Comparison or buying guide Can the claim be trusted? Reviews, proof, external validation Reviews and credible sources Did visibility improve? Impressions, recommendations, referrals, sales Merchant and analytics data Traditional ecommerce SEO still supports crawling and discoverability. This GEO vs AEO vs SEO comparison helps explain the overlap, while ecommerce GEO extends the target toward generated product recommendations that can shape the shortlist before an organic click happens. Why Do Strong Ecommerce Products Still Get Missed by AI? Good products can remain invisible when their public information is incomplete, generic, inconsistent, or difficult to compare. An AI system may identify the SKU without understanding who should buy it. Another product can win because its surrounding information better addresses the shopper’s constraints. We call this the product evidence gap. It appears when product quality exceeds the information available about that product, leaving AI systems with too little context to understand the fit, explain trade-offs, or confidently recommend the item for a detailed shopping request. Product facts are incomplete: A backpack may have excellent rain protection, yet the page never clearly states the laptop size, empty weight, or water resistance. A detailed commuting prompt can favor another option because its visible information makes the buying fit easier to judge. Specifications lack buying meaning: A mattress page may list foam density without explaining which sleeping preferences it suits. The facts exist, yet the shopper still cannot understand the practical difference between two models or why one specification should influence the final choice. Independent evidence is weak: Product pages naturally make the retailer’s strongest case. Specific customer reviews and credible external sources can show how claims hold during real use, especially when the purchase requires more confidence, comparison, or evidence before a buyer decides. Different sources can conflict: price, stock, variant names, or specifications can drift across feeds and webpages. Conflicting facts create uncertainty when an AI system needs current information to narrow a shortlist and determine which product is genuinely available for the shopper’s request. An AI content gap analysis should therefore examine product evidence as closely as missing topics. That diagnosis shows whether the next fix belongs in the catalog, PDP, supporting content, or external source ecosystem. What Information a Product Must Provide Before AI Can Recommend It? A recommendable product needs more than complete specifications. AI systems must recognize the exact item, map its attributes to
A shopper can now ask for lightweight running shoes under ₹8,000 for wide feet and hot weather. AI shopping can narrow hundreds of options before the shopper reaches an ecommerce website. This changes which products enter consideration before any retailer receives a visit. This shift changes GEO for ecommerce. Brands must provide AI systems with sufficiently reliable information to identify and compare products. They must also explain their fit for the shopping situation. Category rankings still matter, yet they no longer cover the complete discovery journey. NIQ found that 42% of consumers had used an AI tool for shopping during the previous month in May 2026. AI is entering product decisions before many retailers have adapted their content systems. Early product understanding is already a practical visibility problem. This blog will help you understand how GEO for ecommerce helps brands improve their AI citations. Key Takeaways GEO for ecommerce improves product understanding before AI systems build shortlists for shoppers. Strong product feeds establish facts while editorial content explains real buying fit. AI shopping prompts combine needs, budgets, preferences, constraints, and product trade-offs. Product pages need decision context instead of repeating specifications or promotional claims. Reviews help AI systems assess real usage beyond retailer-controlled product descriptions online. Large catalogs should prioritize recommendation opportunities rather than optimizing every SKU equally. Google Merchant Center now reports AI shopping visibility for eligible Indian merchants. Ecommerce GEO succeeds when recommendation visibility connects with qualified visits and revenue. How Has AI Shopping Changed What Ecommerce Brands Need to Optimize? AI shopping has shifted product discovery from keyword matching toward constraint matching. Shoppers can describe price limits, intended use, preferences, dimensions, performance needs, and known concerns in a single prompt. Brands must therefore optimize the information needed to narrow options, rather than focusing only on individual category keywords. Google supports conversational shopping across AI Mode and Gemini in India. Its systems combine listings with prices, reviews, inventory information, and product-specific comparisons. The Shopping Graph contained over 60 billion listings by May 2026. Shoppers can therefore compare products across an enormous catalog. ChatGPT follows a similar path. OpenAI says shoppers can refine their choices based on budget, preferences, and constraints, then compare suitable options side by side. Product discovery can use merchant feeds through the Agentic Commerce Protocol alongside public retail information. Our AI search trends analysis explains this broader move toward AI-led shortlisting. Ecommerce brands experience it most directly because generated recommendations can decide which products earn further consideration before shoppers search for a specific retailer or brand. What Features Does GEO for Ecommerce Optimize? GEO for ecommerce improves the information environment surrounding a product so AI systems can understand when it fits a shopper’s request. It connects current product data with useful page content, supporting buying information, external evidence, and measurement. Each layer solves a different problem within the recommendation process. This is broader than a schema project or another product description rewrite. The broader discipline of Generative Engine Optimization explains how brands become understandable across generative discovery. Ecommerce introduces rapidly changing commercial facts and purchase-specific evidence, so AI systems need more than editorial authority as product details change. Our guide to GEO services provides the wider context for this source ecosystem. Product discovery adds another layer because merchant feeds, product pages, reviews, buying guides, and external sources can all shape how a product is identified, compared, or recommended. Recommendation Question Information Needed Best Source Is the product available? Identity, price, stock, seller information Feed and product page Does it match the request? Attributes, size, compatibility, intended use Product data and copy Which option fits better? Differences, trade-offs, suitability Comparison or buying guide Can the claim be trusted? Reviews, proof, external validation Reviews and credible sources Did visibility improve? Impressions, recommendations, referrals, sales Merchant and analytics data Traditional ecommerce SEO still supports crawling and discoverability. This GEO vs AEO vs SEO comparison helps explain the overlap, while ecommerce GEO extends the target toward generated product recommendations that can shape the shortlist before an organic click happens. Why Do Strong Ecommerce Products Still Get Missed by AI? Good products can remain invisible when their public information is incomplete, generic, inconsistent, or difficult to compare. An AI system may identify the SKU without understanding who should buy it. Another product can win because its surrounding information better addresses the shopper’s constraints. We call this the product evidence gap. It appears when product quality exceeds the information available about that product, leaving AI systems with too little context to understand the fit, explain trade-offs, or confidently recommend the item for a detailed shopping request. Product facts are incomplete: A backpack may have excellent rain protection, yet the page never clearly states the laptop size, empty weight, or water resistance. A detailed commuting prompt can favor another option because its visible information makes the buying fit easier to judge. Specifications lack buying meaning: A mattress page may list foam density without explaining which sleeping preferences it suits. The facts exist, yet the shopper still cannot understand the practical difference between two models or why one specification should influence the final choice. Independent evidence is weak: Product pages naturally make the retailer’s strongest case. Specific customer reviews and credible external sources can show how claims hold during real use, especially when the purchase requires more confidence, comparison, or evidence before a buyer decides. Different sources can conflict: price, stock, variant names, or specifications can drift across feeds and webpages. Conflicting facts create uncertainty when an AI system needs current information to narrow a shortlist and determine which product is genuinely available for the shopper’s request. An AI content gap analysis should therefore examine product evidence as closely as missing topics. That diagnosis shows whether the next fix belongs in the catalog, PDP, supporting content, or external source ecosystem. What Information a Product Must Provide Before AI Can Recommend It? A recommendable product needs more than complete specifications. AI systems must recognize the exact item, map its attributes to
Knowledge Graph
A knowledge graph organizes information by connecting identifiable entities with their attributes and relationships. Instead of storing facts as isolated records, it shows how people, organizations, products, places, concepts, and events relate. This structure provides search systems with more context when they need to understand subjects with similar names or related meanings. Google uses its Knowledge Graph to understand facts about real-world entities and the relationships between them. This information can support several Search experiences, including Knowledge Panels. For brands, knowledge graph SEO therefore focuses on consistent entity information, clear relationships, useful content, and supporting signals rather than chasing one search feature. Key Takeaways Knowledge graphs connect identifiable entities through attributes, facts, and relationships. Google’s Knowledge Graph helps Search understand real-world people, places, and things. A Knowledge Panel is different from the underlying Google Knowledge Graph. Consistent entity information can reduce ambiguity across important search sources. Structured data can provide explicit clues about entities and relationships. Knowledge Graph visibility cannot be guaranteed through schema or SEO tactics. Strong entity foundations also support AEO, GEO, and AI search work. What Is a Knowledge Graph and How Does It Organize Information? A knowledge graph organizes information as connected entities rather than isolated records, giving systems more context for each subject. An entity may represent a person, company, product, place, event, or concept, while relationships show how those subjects connect. Google introduced its Knowledge Graph around the idea of understanding real-world “things” and their relationships instead of matching words alone. This shift also supports broader AI search optimization, where systems increasingly need to interpret subjects, contexts, and relationships across diverse discovery experiences. For example, a graph can connect a founder with a company, that company with a product, and the product with its category. These connected facts provide more useful context than separate records because each relationship explains how one identifiable subject relates to another. What Are Entities, Attributes, and Relationships in a Knowledge Graph? Knowledge graphs become easier to understand when their structure is reduced to three elements. Entities represent the subjects being described, attributes add facts about those subjects, and relationships connect one entity with another. Together, these elements turn separate information into a connected model. Element What It Represents Simple Example Why It Adds Context Entity An identifiable person, company, product, place, event, or concept Scribblers India is an organization entity Establishes the subject being described Attribute A fact or characteristic connected with a specific entity The organization provides content strategy services Adds descriptive information about the entity Relationship A connection showing how two separate entities relate A founder works for an organization Connects subjects within a wider information network Identifier Information that helps distinguish one entity from another Official website or recognized database identifier Reduces confusion between entities sharing similar names Consider a simple entity relationship: Scribblers India → provides → content strategy services. Another relationship could connect Scribblers India → operates in → India. A founder entity could then connect with the same organization through a professional role. These relationships do not create Google Knowledge Graph inclusion by themselves. They demonstrate how connected information provides more meaning than an isolated company name, service phrase, or person reference. How Is Google’s Knowledge Graph Different From a Knowledge Panel? Google’s Knowledge Graph and Knowledge Panels are closely connected, although they describe different parts of the search experience. The Knowledge Graph is Google’s underlying system for organizing entity information, while a Knowledge Panel is a visible search feature that can display selected facts. Area Google Knowledge Graph Knowledge Panel What Brands Should Understand What it is Stores connected facts and relationships about identifiable real-world entities Displays selected entity information directly within Google Search results A panel represents one possible use of graph information Where it appears Works behind several Search systems and entity understanding processes Appears visibly beside or within relevant search result pages Entity recognition does not guarantee a visible panel What it contains Connects entities, attributes, identifiers, facts, and related subjects Shows selected facts, images, links, summaries, and related details Panel content reflects only part of available entity information How it develops Google builds entity understanding from multiple available information sources Google generates panels automatically when systems consider them useful Businesses cannot create panels through one SEO action Knowledge Panels therefore represent one answer-led search surface rather than the complete Knowledge Graph itself. This distinction also matters for Answer Engine Optimization, which encompasses broader opportunities to improve visibility across direct-answer experiences rather than focusing on a single Google feature. Where Does Google Get Knowledge Graph Information From? Google builds its Knowledge Graph understanding from several source types rather than relying on a single website or database. Google says its systems gather facts from information shared across the web, as well as open-source resources, licensed databases, structured information, and other sources specific to specific subject areas. Google can use information found across webpages when its systems identify facts about people, places, organizations, and other entities. Open-source knowledge resources can provide established facts and relationships that support understanding of entities across widely documented public subjects. Licensed data sources can supply structured information for areas such as music, sports, television, and other specialized search categories. Structured data on websites can provide explicit clues about organizations, people, products, events, and relationships represented within visible page content. Official business information can help Google understand names, logos, contact details, locations, and other attributes connected with organizations. Google can also use feedback from verified representatives when eligible entity owners report inaccurate information appearing within supported Search features. This mix explains why brands cannot build knowledge graph visibility from a single website field or database listing. Strong entity information needs agreement across owned content, suitable structured data, and credible external sources that have a real reason to describe the organization. Knowledge graph understanding can also support answer-led search when systems need to identify the organization, person, or concept behind a response. Our Answer Engine Optimization services address the broader visibility problem by
A knowledge graph organizes information by connecting identifiable entities with their attributes and relationships. Instead of storing facts as isolated records, it shows how people, organizations, products, places, concepts, and events relate. This structure provides search systems with more context when they need to understand subjects with similar names or related meanings. Google uses its Knowledge Graph to understand facts about real-world entities and the relationships between them. This information can support several Search experiences, including Knowledge Panels. For brands, knowledge graph SEO therefore focuses on consistent entity information, clear relationships, useful content, and supporting signals rather than chasing one search feature. Key Takeaways Knowledge graphs connect identifiable entities through attributes, facts, and relationships. Google’s Knowledge Graph helps Search understand real-world people, places, and things. A Knowledge Panel is different from the underlying Google Knowledge Graph. Consistent entity information can reduce ambiguity across important search sources. Structured data can provide explicit clues about entities and relationships. Knowledge Graph visibility cannot be guaranteed through schema or SEO tactics. Strong entity foundations also support AEO, GEO, and AI search work. What Is a Knowledge Graph and How Does It Organize Information? A knowledge graph organizes information as connected entities rather than isolated records, giving systems more context for each subject. An entity may represent a person, company, product, place, event, or concept, while relationships show how those subjects connect. Google introduced its Knowledge Graph around the idea of understanding real-world “things” and their relationships instead of matching words alone. This shift also supports broader AI search optimization, where systems increasingly need to interpret subjects, contexts, and relationships across diverse discovery experiences. For example, a graph can connect a founder with a company, that company with a product, and the product with its category. These connected facts provide more useful context than separate records because each relationship explains how one identifiable subject relates to another. What Are Entities, Attributes, and Relationships in a Knowledge Graph? Knowledge graphs become easier to understand when their structure is reduced to three elements. Entities represent the subjects being described, attributes add facts about those subjects, and relationships connect one entity with another. Together, these elements turn separate information into a connected model. Element What It Represents Simple Example Why It Adds Context Entity An identifiable person, company, product, place, event, or concept Scribblers India is an organization entity Establishes the subject being described Attribute A fact or characteristic connected with a specific entity The organization provides content strategy services Adds descriptive information about the entity Relationship A connection showing how two separate entities relate A founder works for an organization Connects subjects within a wider information network Identifier Information that helps distinguish one entity from another Official website or recognized database identifier Reduces confusion between entities sharing similar names Consider a simple entity relationship: Scribblers India → provides → content strategy services. Another relationship could connect Scribblers India → operates in → India. A founder entity could then connect with the same organization through a professional role. These relationships do not create Google Knowledge Graph inclusion by themselves. They demonstrate how connected information provides more meaning than an isolated company name, service phrase, or person reference. How Is Google’s Knowledge Graph Different From a Knowledge Panel? Google’s Knowledge Graph and Knowledge Panels are closely connected, although they describe different parts of the search experience. The Knowledge Graph is Google’s underlying system for organizing entity information, while a Knowledge Panel is a visible search feature that can display selected facts. Area Google Knowledge Graph Knowledge Panel What Brands Should Understand What it is Stores connected facts and relationships about identifiable real-world entities Displays selected entity information directly within Google Search results A panel represents one possible use of graph information Where it appears Works behind several Search systems and entity understanding processes Appears visibly beside or within relevant search result pages Entity recognition does not guarantee a visible panel What it contains Connects entities, attributes, identifiers, facts, and related subjects Shows selected facts, images, links, summaries, and related details Panel content reflects only part of available entity information How it develops Google builds entity understanding from multiple available information sources Google generates panels automatically when systems consider them useful Businesses cannot create panels through one SEO action Knowledge Panels therefore represent one answer-led search surface rather than the complete Knowledge Graph itself. This distinction also matters for Answer Engine Optimization, which encompasses broader opportunities to improve visibility across direct-answer experiences rather than focusing on a single Google feature. Where Does Google Get Knowledge Graph Information From? Google builds its Knowledge Graph understanding from several source types rather than relying on a single website or database. Google says its systems gather facts from information shared across the web, as well as open-source resources, licensed databases, structured information, and other sources specific to specific subject areas. Google can use information found across webpages when its systems identify facts about people, places, organizations, and other entities. Open-source knowledge resources can provide established facts and relationships that support understanding of entities across widely documented public subjects. Licensed data sources can supply structured information for areas such as music, sports, television, and other specialized search categories. Structured data on websites can provide explicit clues about organizations, people, products, events, and relationships represented within visible page content. Official business information can help Google understand names, logos, contact details, locations, and other attributes connected with organizations. Google can also use feedback from verified representatives when eligible entity owners report inaccurate information appearing within supported Search features. This mix explains why brands cannot build knowledge graph visibility from a single website field or database listing. Strong entity information needs agreement across owned content, suitable structured data, and credible external sources that have a real reason to describe the organization. Knowledge graph understanding can also support answer-led search when systems need to identify the organization, person, or concept behind a response. Our Answer Engine Optimization services address the broader visibility problem by
Query Fan-Out
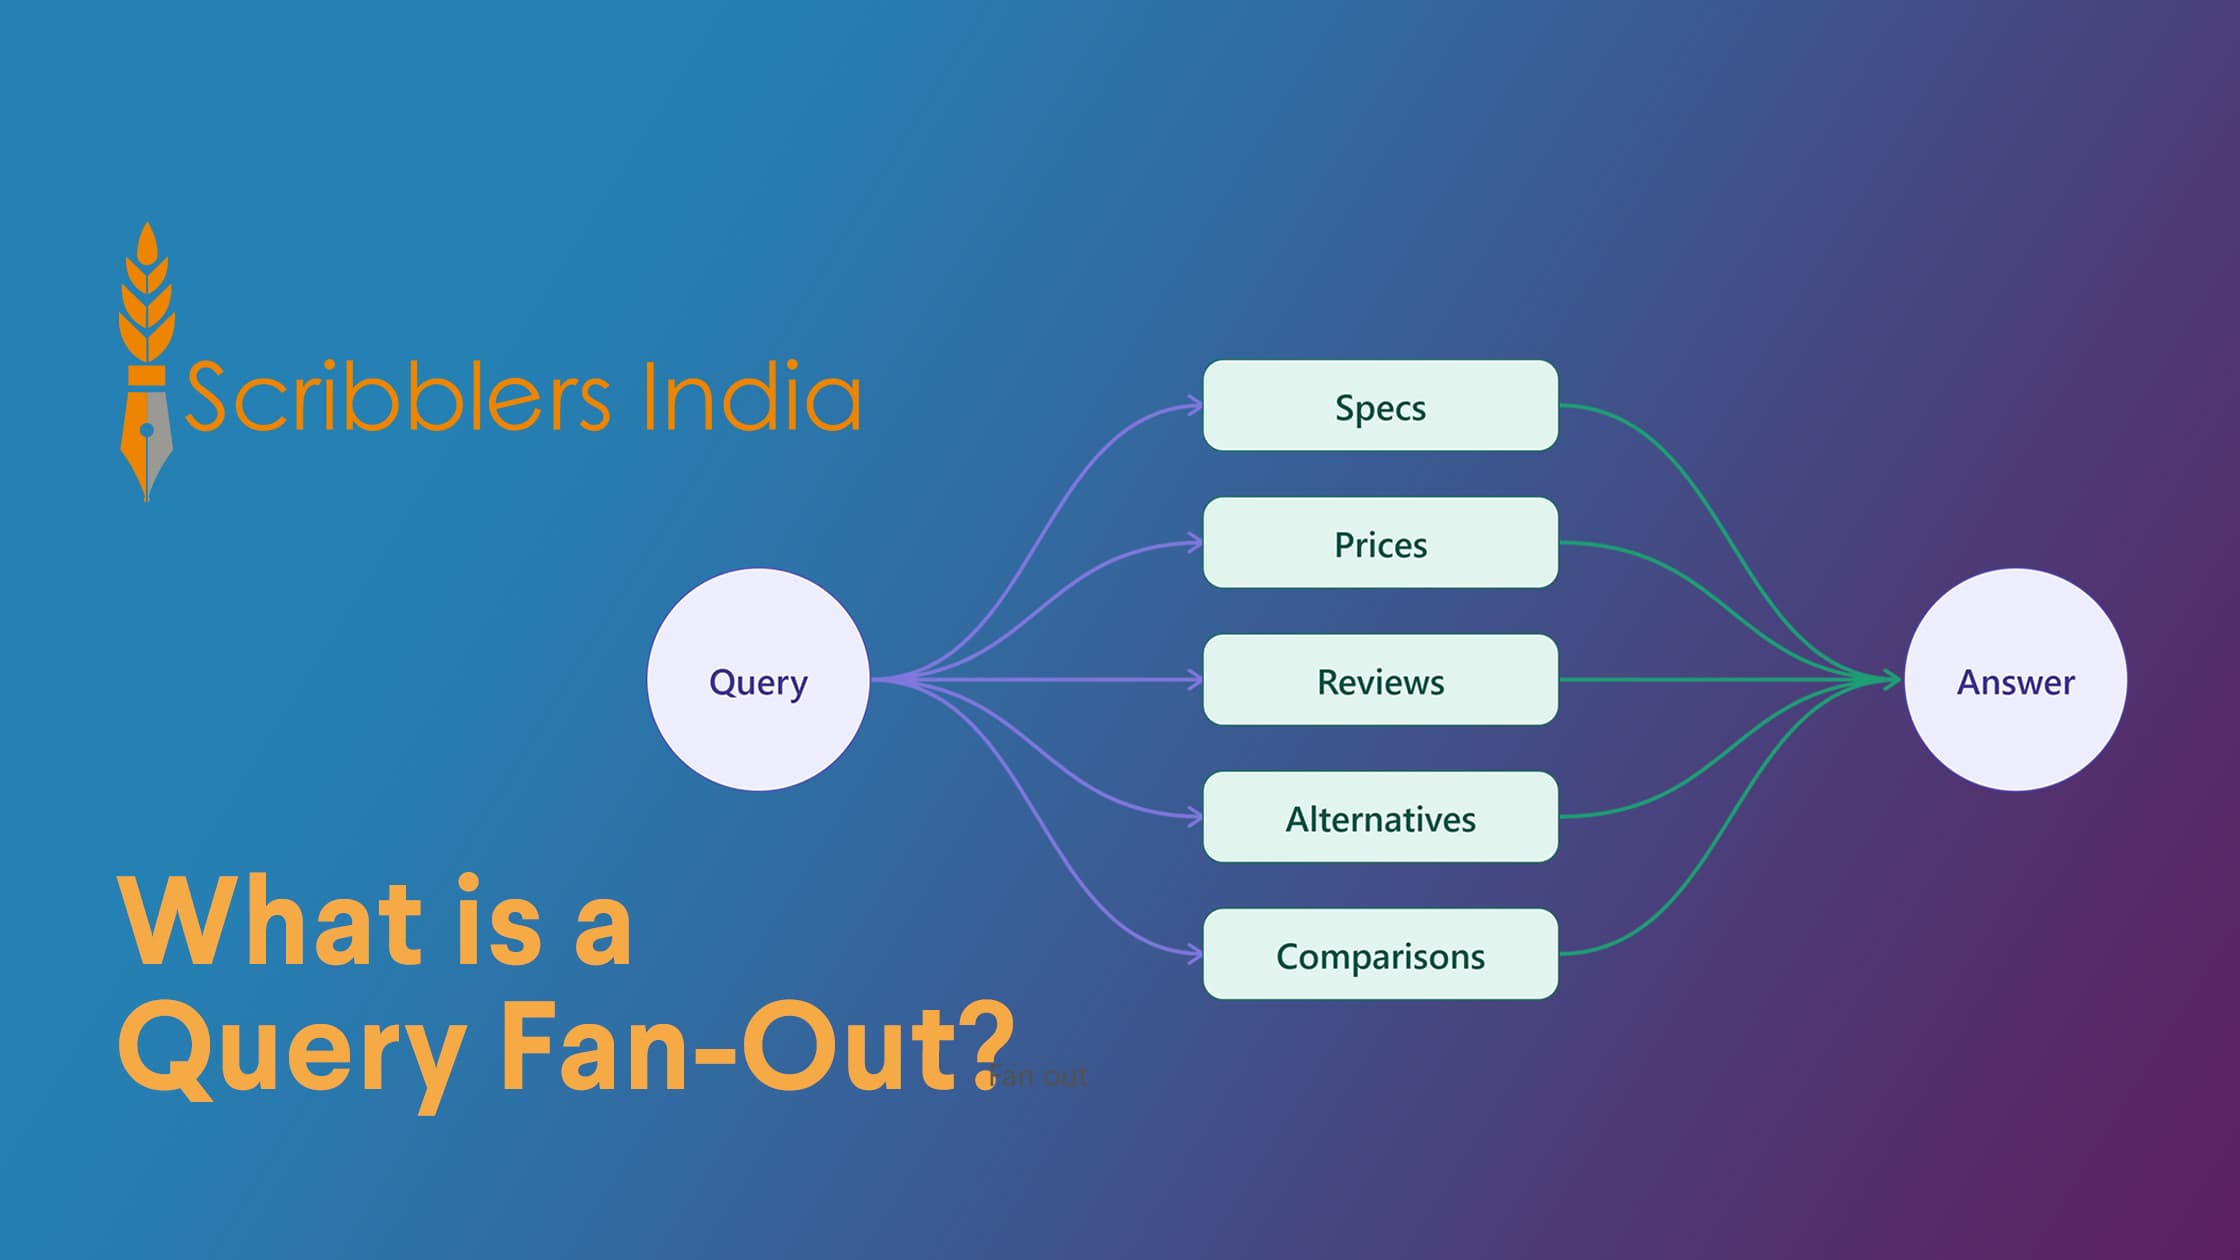
Query fan-out is a search technique that expands a single user question into several related searches or subtopics before generating a response. Instead of relying on the original wording alone, an AI search system can gather information across different angles, helping it address complex questions that would previously require several separate searches. Google uses query fan-out within AI Mode and says AI Overviews may also use the technique. For content teams, this changes how search demand should be interpreted. One visible prompt can represent several hidden information needs, making useful topic coverage and connected supporting content more important than targeting a single phrase. Key Takeaways Query fan-out expands one search into several related information requests. Google uses the technique within AI Mode and generative Search. Google does not publish one fixed number of fan-out queries. Fan-out can explore subtopics, comparisons, constraints, and supporting information. Content strategies should address related needs without creating repetitive pages. Strong topic coverage can improve relevance across several related search paths. Measurement should examine page visibility rather than invented fan-out rankings. What Is Query Fan-Out and How Does It Work? Query fan-out allows an AI search system to explore multiple aspects of a single request before preparing an answer. Google defines it as concurrent related queries generated to request more information and retrieve additional search results relevant to the original user question. For example, a question about repairing a weed-filled lawn might lead Google to explore herbicides, chemical-free removal, and prevention methods. The user enters one question, while Search gathers supporting information across several connected angles before producing the response. This retrieval stage connects query fan-out with Retrieval-Augmented Generation. Both involve gathering external information before generation, although query fan-out describes how a single information need can expand into several retrieval paths rather than a single search request. How Is Query Fan-Out Different From Traditional Search? Traditional search usually begins with one visible query and returns results relevant to that search. Query fan-out can expand the same request into several related searches before an AI-generated response appears. This creates a broader retrieval process behind a single visible user interaction. Area Traditional Search Query Fan-Out Content Implication Starting point One submitted query guides the initial search results returned One query can trigger several connected background searches One visible prompt may contain several information needs Search scope Results primarily address the submitted search and interpreted intent Searches can explore multiple subtopics around the original question Supporting angles can become relevant within one journey User effort People may perform additional searches as their research develops The system can perform related searches on the user’s behalf Content should anticipate natural follow-up information needs Final experience Users usually review individual search results before continuing research AI systems can combine retrieved information into one response Different pages may contribute to the same generated answer Query fan-out is also narrower than the broad concept of query expansion. Search engines have expanded and interpreted queries for years. Query fan-out refers to concurrent, related searches used in newer generative Search experiences to gather broader supporting information. What Does Query Fan-Out Look Like in a Real Search Journey? A useful way to understand query fan-out is to examine a complex buyer question that contains several hidden decisions. The exact searches generated remain platform-controlled, so marketers should treat possible fan-out questions as research hypotheses rather than a list of queries Google has confirmed. Consider this prompt: “Which payroll system works for a growing company with remote employees across several US states?” Possible Subtopic Illustrative Related Search Information Required Useful Content Asset Multi-state compliance Payroll software for employees across multiple US states State payroll requirements and compliance capabilities Detailed product or compliance guide Scalability Payroll platforms suitable for growing employee numbers Limits, workflows, automation, and expansion support Product capability page or comparison Remote workforce Payroll software supporting distributed employee teams Employee access, onboarding, and location requirements Remote payroll or workforce guide Integrations Payroll systems connecting with HR and accounting tools Supported platforms, workflows, and data connections Integration pages or platform documentation Evaluation Features businesses should compare before choosing payroll software Selection criteria, costs, support, and implementation Buyer guide or comparison page These examples illustrate possible branches rather than Google’s internal searches. Google does not publish a single universal fan-out formula, and search results can vary with the original question, available context, Search systems, and the information needed for the response. Why Does Query Fan-Out Change SEO Content Planning? Query fan-out broadens the information space surrounding a single visible search. Content teams therefore need to understand the questions connected with a topic without turning every possible variation into another page. Google specifically warns against producing separate content for every fan-out query primarily to influence generative Search. Keyword research should identify the central search need before teams expand coverage into connected questions and supporting information. Related queries must reveal missing information within existing pages before they automatically become topics for separate new articles. Broader buyer questions can reveal several related decision criteria that warrant coverage in a single useful guide or content cluster. Separate pages remain appropriate when the underlying intent changes enough to require a distinct answer, format, or user journey. Internal links can connect supporting resources within a single topic when several pages contribute useful information to the same research journey. Content calendars should prioritize meaningful information gaps over query volume to reduce duplicate pages created by minor wording variations. This is where a broader content strategy becomes more useful than keyword expansion alone. Teams need to decide what belongs on one page, what deserves supporting content, and which apparent gaps already have sufficient coverage. How Can Teams Find Likely Query Fan-Out Opportunities? Google does not provide marketers with a complete list of every background search generated for each user prompt. Teams can still identify probable information branches by studying real search behavior, customer questions, existing content gaps, and the supporting decisions users make around important topics. Search results might
Query fan-out is a search technique that expands a single user question into several related searches or subtopics before generating a response. Instead of relying on the original wording alone, an AI search system can gather information across different angles, helping it address complex questions that would previously require several separate searches. Google uses query fan-out within AI Mode and says AI Overviews may also use the technique. For content teams, this changes how search demand should be interpreted. One visible prompt can represent several hidden information needs, making useful topic coverage and connected supporting content more important than targeting a single phrase. Key Takeaways Query fan-out expands one search into several related information requests. Google uses the technique within AI Mode and generative Search. Google does not publish one fixed number of fan-out queries. Fan-out can explore subtopics, comparisons, constraints, and supporting information. Content strategies should address related needs without creating repetitive pages. Strong topic coverage can improve relevance across several related search paths. Measurement should examine page visibility rather than invented fan-out rankings. What Is Query Fan-Out and How Does It Work? Query fan-out allows an AI search system to explore multiple aspects of a single request before preparing an answer. Google defines it as concurrent related queries generated to request more information and retrieve additional search results relevant to the original user question. For example, a question about repairing a weed-filled lawn might lead Google to explore herbicides, chemical-free removal, and prevention methods. The user enters one question, while Search gathers supporting information across several connected angles before producing the response. This retrieval stage connects query fan-out with Retrieval-Augmented Generation. Both involve gathering external information before generation, although query fan-out describes how a single information need can expand into several retrieval paths rather than a single search request. How Is Query Fan-Out Different From Traditional Search? Traditional search usually begins with one visible query and returns results relevant to that search. Query fan-out can expand the same request into several related searches before an AI-generated response appears. This creates a broader retrieval process behind a single visible user interaction. Area Traditional Search Query Fan-Out Content Implication Starting point One submitted query guides the initial search results returned One query can trigger several connected background searches One visible prompt may contain several information needs Search scope Results primarily address the submitted search and interpreted intent Searches can explore multiple subtopics around the original question Supporting angles can become relevant within one journey User effort People may perform additional searches as their research develops The system can perform related searches on the user’s behalf Content should anticipate natural follow-up information needs Final experience Users usually review individual search results before continuing research AI systems can combine retrieved information into one response Different pages may contribute to the same generated answer Query fan-out is also narrower than the broad concept of query expansion. Search engines have expanded and interpreted queries for years. Query fan-out refers to concurrent, related searches used in newer generative Search experiences to gather broader supporting information. What Does Query Fan-Out Look Like in a Real Search Journey? A useful way to understand query fan-out is to examine a complex buyer question that contains several hidden decisions. The exact searches generated remain platform-controlled, so marketers should treat possible fan-out questions as research hypotheses rather than a list of queries Google has confirmed. Consider this prompt: “Which payroll system works for a growing company with remote employees across several US states?” Possible Subtopic Illustrative Related Search Information Required Useful Content Asset Multi-state compliance Payroll software for employees across multiple US states State payroll requirements and compliance capabilities Detailed product or compliance guide Scalability Payroll platforms suitable for growing employee numbers Limits, workflows, automation, and expansion support Product capability page or comparison Remote workforce Payroll software supporting distributed employee teams Employee access, onboarding, and location requirements Remote payroll or workforce guide Integrations Payroll systems connecting with HR and accounting tools Supported platforms, workflows, and data connections Integration pages or platform documentation Evaluation Features businesses should compare before choosing payroll software Selection criteria, costs, support, and implementation Buyer guide or comparison page These examples illustrate possible branches rather than Google’s internal searches. Google does not publish a single universal fan-out formula, and search results can vary with the original question, available context, Search systems, and the information needed for the response. Why Does Query Fan-Out Change SEO Content Planning? Query fan-out broadens the information space surrounding a single visible search. Content teams therefore need to understand the questions connected with a topic without turning every possible variation into another page. Google specifically warns against producing separate content for every fan-out query primarily to influence generative Search. Keyword research should identify the central search need before teams expand coverage into connected questions and supporting information. Related queries must reveal missing information within existing pages before they automatically become topics for separate new articles. Broader buyer questions can reveal several related decision criteria that warrant coverage in a single useful guide or content cluster. Separate pages remain appropriate when the underlying intent changes enough to require a distinct answer, format, or user journey. Internal links can connect supporting resources within a single topic when several pages contribute useful information to the same research journey. Content calendars should prioritize meaningful information gaps over query volume to reduce duplicate pages created by minor wording variations. This is where a broader content strategy becomes more useful than keyword expansion alone. Teams need to decide what belongs on one page, what deserves supporting content, and which apparent gaps already have sufficient coverage. How Can Teams Find Likely Query Fan-Out Opportunities? Google does not provide marketers with a complete list of every background search generated for each user prompt. Teams can still identify probable information branches by studying real search behavior, customer questions, existing content gaps, and the supporting decisions users make around important topics. Search results might
Semantic Search
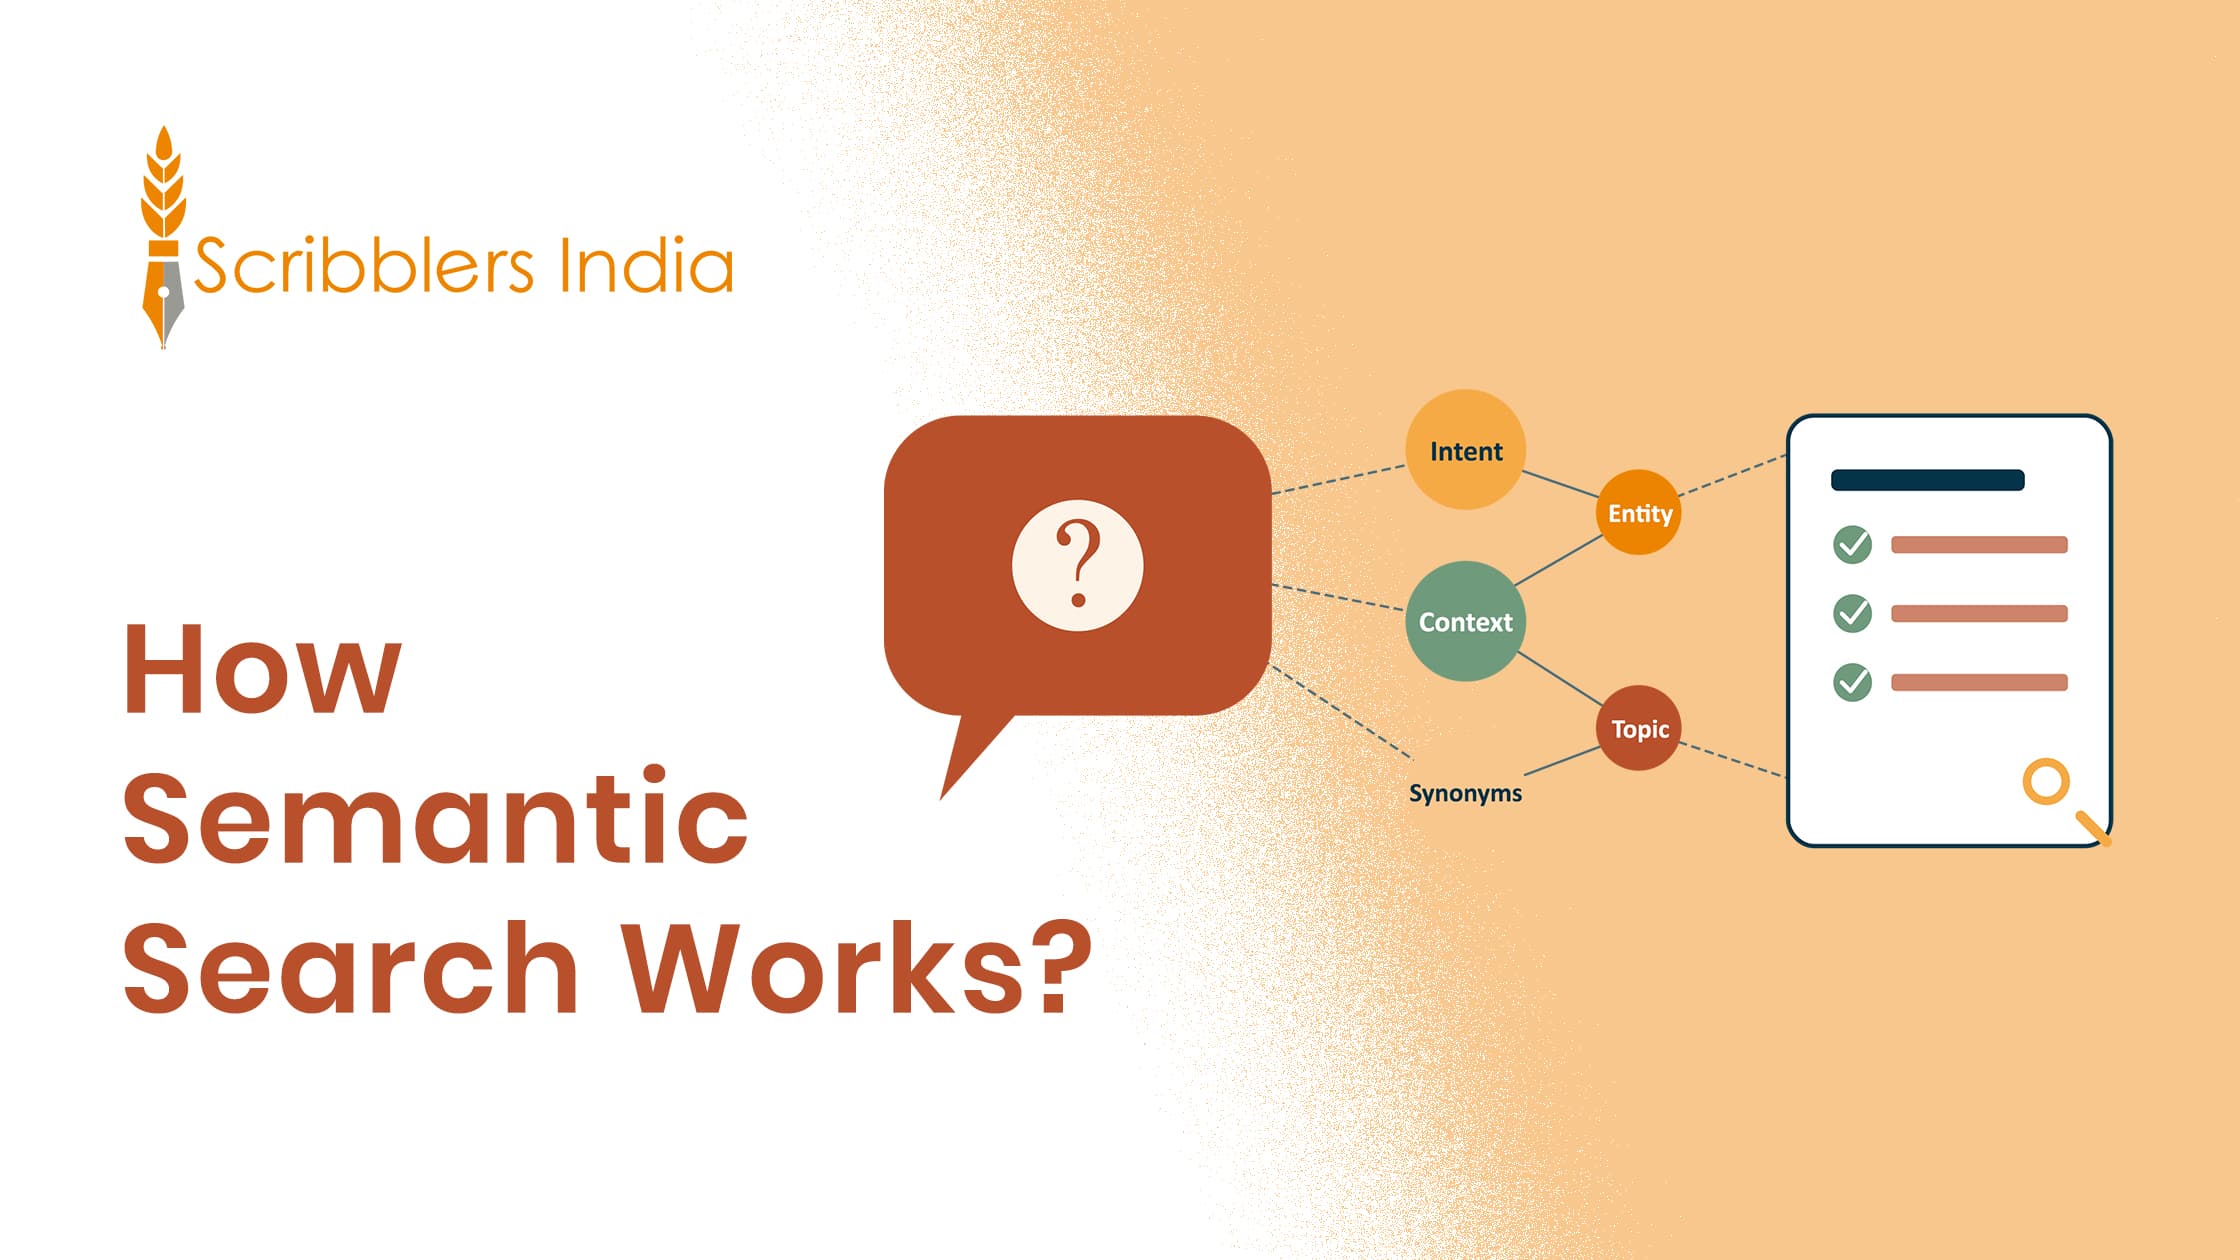
Semantic search is a search approach that focuses on meaning, context, and user intent instead of relying on exact keyword matches. It helps search systems understand what people want, how words relate, and which concepts or entities can answer a query. This allows relevant information to surface even when wording differs. Modern search engines use language models, neural matching, entities, and other systems to interpret queries and webpages. For marketers, semantic search changes content planning from keyword repetition toward useful topic coverage, clear relationships, and search intent. These principles also support retrieval across AI-powered search experiences and RAG systems. Key Takeaways: Semantic search focuses on the meaning of a query rather than exact word matching. Search intent helps systems understand what information users want. Entities provide identifiable subjects that connect concepts across different webpages. Embeddings can represent meaning through numerical relationships between words and documents. Keyword matching remains useful when exact terms carry important search meaning. Strong content should address genuine questions rather than repeating keyword variations. Semantic retrieval also supports many RAG and AI search applications. What Is Semantic Search and How Does It Work? Semantic search seeks information that matches the meaning of a query rather than requiring the same words inside each result. It considers context, intent, concepts, entities, and relationships to identify information that satisfies the searcher’s query. Google has developed several systems that support this broader language understanding. RankBrain connects unfamiliar wording with related concepts, while neural matching evaluates wider representations of queries and pages. BERT examines how words relate within a sequence to understand context and meaning. Consider a search for “affordable phones with strong cameras.” A useful result might discuss “budget smartphones for photography” without repeating the original wording. Semantic understanding can connect both phrases through their shared concepts, while literal matching would place greater weight on identical terms. This does not mean keywords have disappeared from search. Exact wording can remain valuable for product codes, names, technical terms, and queries where specific language changes the intended meaning. How Is Semantic Search Different From Keyword Search? Keyword search looks for direct matches between words in a query and words found inside documents. Semantic search expands that process by considering meaning and relationships. Modern retrieval systems often combine both approaches because exact terminology and conceptual similarity solve different search problems. Area Keyword Search Semantic Search Simple Example Focus Matches query terms with words appearing inside indexed documents. Matches the meaning and concepts represented across queries and documents. “Cheap laptop” can connect with “affordable notebook computer.” Synonyms Different wording can weaken matching when exact terms are absent. Related words can connect when they represent a similar underlying concept. “Attorney” can relate to content discussing a “lawyer.” Ambiguity One word may retrieve different subjects sharing the same wording. Context can help determine which meaning the searcher most likely intended. “Jaguar” may mean an animal, vehicle, or brand. Best use Exact identifiers and specialized terminology often benefit from direct matching. Conversational questions and concept-led queries benefit from meaning-based retrieval. Product codes favor exact search; research questions need context. Semantic search should therefore complement keyword research rather than replace it. Search teams still need the language audiences use while understanding the questions, concepts, and relationships behind those words. Which Signals Help Search Systems Understand Meaning? Meaning can come from several parts of a query or document working together, rather than from a single isolated keyword. Search systems examine language patterns and context to connect a request to relevant information, while different search technologies may weigh these inputs differently. Search intent helps distinguish whether a user wants information, a website, a comparison, a product, or another outcome. Word relationships provide context when the meaning of one term changes according to surrounding words within the query. Entities identify distinct subjects such as companies, people, products, places, events, and concepts referenced within search content. Synonyms connect related language when users and publishers describe the same idea through different words or common expressions. Page context clarifies meaning by showing how headings, supporting explanations, examples, and related concepts fit within one subject. Previous search context can help some search experiences interpret follow-up requests when earlier interactions provide useful information about intent. Google explains that BERT considers words in relation to surrounding words rather than processing each term in isolation. Neural matching can also connect broader concepts represented within queries and webpages. How Do Entities, Embeddings, and Context Support Semantic Search? Entities, embeddings, and context support different parts of semantic understanding. An entity identifies a recognizable subject; context helps establish what words mean within a request; and embeddings represent semantic similarity between pieces of information using numerical representations. An entity could represent Microsoft, Mumbai, a specific product, or a recognized business concept. Relationships between entities add further context. A search engine may connect a company with its founder, products, industry, location, and other subjects represented across available information. Embeddings take a different approach. Google Cloud explains that semantic search systems can transform text into vectors that represent meaning. Texts with similar meanings can then appear closer within this mathematical space, allowing retrieval even when their exact wording differs. Context helps resolve the remaining ambiguity. A search for “apple support near me” provides enough surrounding information to suggest a technology brand. A search for “apple varieties for baking” points toward fruit, even though both queries contain the same central word. How Does Semantic Search Change SEO Content Planning? Semantic search reduces the value of creating separate pages for every small keyword variation when those searches share the same underlying intent. Strong planning starts by understanding what users need, which concepts support the answer, and where separate pages represent genuinely different information requirements. Content teams should group keywords sharing the same intent before deciding whether each variation deserves another independent page. Writers should cover supporting questions and concepts when they help readers understand the main subject without creating unnecessary topical detours. Important entities should receive clear context
Semantic search is a search approach that focuses on meaning, context, and user intent instead of relying on exact keyword matches. It helps search systems understand what people want, how words relate, and which concepts or entities can answer a query. This allows relevant information to surface even when wording differs. Modern search engines use language models, neural matching, entities, and other systems to interpret queries and webpages. For marketers, semantic search changes content planning from keyword repetition toward useful topic coverage, clear relationships, and search intent. These principles also support retrieval across AI-powered search experiences and RAG systems. Key Takeaways: Semantic search focuses on the meaning of a query rather than exact word matching. Search intent helps systems understand what information users want. Entities provide identifiable subjects that connect concepts across different webpages. Embeddings can represent meaning through numerical relationships between words and documents. Keyword matching remains useful when exact terms carry important search meaning. Strong content should address genuine questions rather than repeating keyword variations. Semantic retrieval also supports many RAG and AI search applications. What Is Semantic Search and How Does It Work? Semantic search seeks information that matches the meaning of a query rather than requiring the same words inside each result. It considers context, intent, concepts, entities, and relationships to identify information that satisfies the searcher’s query. Google has developed several systems that support this broader language understanding. RankBrain connects unfamiliar wording with related concepts, while neural matching evaluates wider representations of queries and pages. BERT examines how words relate within a sequence to understand context and meaning. Consider a search for “affordable phones with strong cameras.” A useful result might discuss “budget smartphones for photography” without repeating the original wording. Semantic understanding can connect both phrases through their shared concepts, while literal matching would place greater weight on identical terms. This does not mean keywords have disappeared from search. Exact wording can remain valuable for product codes, names, technical terms, and queries where specific language changes the intended meaning. How Is Semantic Search Different From Keyword Search? Keyword search looks for direct matches between words in a query and words found inside documents. Semantic search expands that process by considering meaning and relationships. Modern retrieval systems often combine both approaches because exact terminology and conceptual similarity solve different search problems. Area Keyword Search Semantic Search Simple Example Focus Matches query terms with words appearing inside indexed documents. Matches the meaning and concepts represented across queries and documents. “Cheap laptop” can connect with “affordable notebook computer.” Synonyms Different wording can weaken matching when exact terms are absent. Related words can connect when they represent a similar underlying concept. “Attorney” can relate to content discussing a “lawyer.” Ambiguity One word may retrieve different subjects sharing the same wording. Context can help determine which meaning the searcher most likely intended. “Jaguar” may mean an animal, vehicle, or brand. Best use Exact identifiers and specialized terminology often benefit from direct matching. Conversational questions and concept-led queries benefit from meaning-based retrieval. Product codes favor exact search; research questions need context. Semantic search should therefore complement keyword research rather than replace it. Search teams still need the language audiences use while understanding the questions, concepts, and relationships behind those words. Which Signals Help Search Systems Understand Meaning? Meaning can come from several parts of a query or document working together, rather than from a single isolated keyword. Search systems examine language patterns and context to connect a request to relevant information, while different search technologies may weigh these inputs differently. Search intent helps distinguish whether a user wants information, a website, a comparison, a product, or another outcome. Word relationships provide context when the meaning of one term changes according to surrounding words within the query. Entities identify distinct subjects such as companies, people, products, places, events, and concepts referenced within search content. Synonyms connect related language when users and publishers describe the same idea through different words or common expressions. Page context clarifies meaning by showing how headings, supporting explanations, examples, and related concepts fit within one subject. Previous search context can help some search experiences interpret follow-up requests when earlier interactions provide useful information about intent. Google explains that BERT considers words in relation to surrounding words rather than processing each term in isolation. Neural matching can also connect broader concepts represented within queries and webpages. How Do Entities, Embeddings, and Context Support Semantic Search? Entities, embeddings, and context support different parts of semantic understanding. An entity identifies a recognizable subject; context helps establish what words mean within a request; and embeddings represent semantic similarity between pieces of information using numerical representations. An entity could represent Microsoft, Mumbai, a specific product, or a recognized business concept. Relationships between entities add further context. A search engine may connect a company with its founder, products, industry, location, and other subjects represented across available information. Embeddings take a different approach. Google Cloud explains that semantic search systems can transform text into vectors that represent meaning. Texts with similar meanings can then appear closer within this mathematical space, allowing retrieval even when their exact wording differs. Context helps resolve the remaining ambiguity. A search for “apple support near me” provides enough surrounding information to suggest a technology brand. A search for “apple varieties for baking” points toward fruit, even though both queries contain the same central word. How Does Semantic Search Change SEO Content Planning? Semantic search reduces the value of creating separate pages for every small keyword variation when those searches share the same underlying intent. Strong planning starts by understanding what users need, which concepts support the answer, and where separate pages represent genuinely different information requirements. Content teams should group keywords sharing the same intent before deciding whether each variation deserves another independent page. Writers should cover supporting questions and concepts when they help readers understand the main subject without creating unnecessary topical detours. Important entities should receive clear context
Entity SEO
Entity SEO helps search engines understand a brand, person, product, place, or concept as a distinct entity rather than a loose collection of keywords. It focuses on identity, attributes, relationships, and supporting context so search systems can connect the right information with the right real-world subject across different search experiences. Entity-based SEO does not replace keyword research or traditional SEO. It adds another layer that explains what a page is about, who or what it represents, and how related information connects. This is useful across Google Search, AI Overviews, ChatGPT, and other systems that interpret topics based on meaning and relationships. Key Takeaways Entity SEO helps search systems distinguish real-world subjects from similar names or phrases. Entities can include organizations, people, products, places, services, concepts, and events. Consistent facts across owned and external sources can strengthen understanding of the entity. Structured data can describe entities without guaranteeing rankings or AI citations. Internal links help connect related people, services, products, topics, and supporting resources. Entity SEO complements keyword SEO rather than replacing established search optimization foundations. Strong entity clarity can support more accurate brand representation across AI search. What Is Entity SEO and What Counts as an Entity? Entity SEO focuses on helping search systems identify a distinct subject and understand the information connected with it. Google introduced its Knowledge Graph around the idea of understanding “things” and their relationships rather than treating every search as a string of words. An entity can represent a person, company, place, product, event, creative work, or recognizable concept. Google describes Knowledge Graph entities through identifiers, names, types, descriptions, images, URLs, and other attributes that help distinguish one subject from another. Consider a software company called ABCS. Search systems need enough context to determine whether ABCD refers to that company, another business, a fictional brand, or another subject sharing the name. The same challenge applies to people. Two consultants may share the same name, while their employers, locations, specialties, websites, profiles, and published work create distinct entity relationships. Entity optimization therefore focuses on identity and context rather than on repeating a company or person’s name across multiple pages. The search system needs sufficient consistent information to understand which entity the page describes and how that entity relates to related subjects. How Is Entity SEO Different From Keyword SEO and Semantic SEO? Keyword SEO, semantic SEO, and entity SEO overlap because modern search interpretation integrates words, meanings, topics, and identifiable subjects. The difference lies in what each approach emphasizes when teams research queries, organize content, and communicate meaning across a website. Approach Focus Typical Question Example Keyword SEO Search phrases and query demand What words does the audience search? Targeting “payroll software Australia” Semantic SEO Meaning, context, and related concepts What wider subject does this query represent? Covering payroll compliance and processing Entity SEO Identifiable subjects and relationships Which company, person, product, or concept is involved? Connecting a payroll platform with its company and features Topic clustering Organized coverage around connected questions Which supporting pages build subject depth? Connecting payroll guides and product pages A strong search strategy does not require choosing one approach and abandoning the others. Keyword research identifies demand, semantic coverage explains meaning, and entity SEO reduces ambiguity around the people, companies, products, and concepts represented. How Do Search Engines Recognize and Connect Entities? Search systems can build entity understanding from information gathered across webpages, structured databases, licensed sources, and other available resources. Google states that its Knowledge Graph maps attributes and relationships between real-world entities using information collected from several source types. A consistent entity name helps systems connect references that describe the same company, person, product, or service. A clear entity type distinguishes whether a name refers to an organization, person, place, product, event, or another subject. Relevant descriptive attributes provide context such as location, occupation, category, ownership, product type, or organizational role. Meaningful entity relationships connect companies with founders, products, locations, services, publications, partners, and other identifiable subjects. Supporting web references can provide corroborating information when credible sources describe the same entity using compatible facts and context. Structured machine-readable information can label entity details when suitable schema types and properties match the visible webpage content. No individual signal guarantees entity status or a search outcome. Search systems combine available information, relationships, and context when determining whether references describe the same subject. Which Signals Help Search Systems Understand a Brand Entity? Brand entity clarity improves when important information agrees across the places where search systems and users encounter the organization. Companies should concentrate on accurate identity, connected owned content, credible external corroboration, and understandable relationships rather than manufacturing large volumes of repetitive mentions. Consistent brand information: Company names, locations, service descriptions, leadership information, and important product names should remain consistent across key owned pages. Small wording variations are natural, although conflicting facts can create uncertainty around identity or current positioning. Clear About and profile pages: An About page should explain what the organization does, who it serves, where it operates, and whom or what it connects with. Founder and author profiles should also explain professional relationships rather than functioning as thin biography pages. Connected service and product information: Important offerings should connect with the organization through descriptive copy, navigation, internal links, and relevant structured data. This helps prevent products or services from appearing as isolated names without clear ownership, category, or business context. Relevant external references: Industry publications, professional profiles, partner websites, customer reviews, directories, interviews, and event pages can provide independent context. These sources are more valuable when they reflect real relationships rather than placements created solely to manufacture entity signals. Accurate structured data: Organization, Person, Product, ProfilePage, and related schema types can describe relevant page information when implemented correctly. Structured data gives search systems explicit clues about page meaning, while Google does not present schema as a guarantee of rankings. Our schema markup for AI search guide explains why structured data should support accurate page information instead of being treated as an
Entity SEO helps search engines understand a brand, person, product, place, or concept as a distinct entity rather than a loose collection of keywords. It focuses on identity, attributes, relationships, and supporting context so search systems can connect the right information with the right real-world subject across different search experiences. Entity-based SEO does not replace keyword research or traditional SEO. It adds another layer that explains what a page is about, who or what it represents, and how related information connects. This is useful across Google Search, AI Overviews, ChatGPT, and other systems that interpret topics based on meaning and relationships. Key Takeaways Entity SEO helps search systems distinguish real-world subjects from similar names or phrases. Entities can include organizations, people, products, places, services, concepts, and events. Consistent facts across owned and external sources can strengthen understanding of the entity. Structured data can describe entities without guaranteeing rankings or AI citations. Internal links help connect related people, services, products, topics, and supporting resources. Entity SEO complements keyword SEO rather than replacing established search optimization foundations. Strong entity clarity can support more accurate brand representation across AI search. What Is Entity SEO and What Counts as an Entity? Entity SEO focuses on helping search systems identify a distinct subject and understand the information connected with it. Google introduced its Knowledge Graph around the idea of understanding “things” and their relationships rather than treating every search as a string of words. An entity can represent a person, company, place, product, event, creative work, or recognizable concept. Google describes Knowledge Graph entities through identifiers, names, types, descriptions, images, URLs, and other attributes that help distinguish one subject from another. Consider a software company called ABCS. Search systems need enough context to determine whether ABCD refers to that company, another business, a fictional brand, or another subject sharing the name. The same challenge applies to people. Two consultants may share the same name, while their employers, locations, specialties, websites, profiles, and published work create distinct entity relationships. Entity optimization therefore focuses on identity and context rather than on repeating a company or person’s name across multiple pages. The search system needs sufficient consistent information to understand which entity the page describes and how that entity relates to related subjects. How Is Entity SEO Different From Keyword SEO and Semantic SEO? Keyword SEO, semantic SEO, and entity SEO overlap because modern search interpretation integrates words, meanings, topics, and identifiable subjects. The difference lies in what each approach emphasizes when teams research queries, organize content, and communicate meaning across a website. Approach Focus Typical Question Example Keyword SEO Search phrases and query demand What words does the audience search? Targeting “payroll software Australia” Semantic SEO Meaning, context, and related concepts What wider subject does this query represent? Covering payroll compliance and processing Entity SEO Identifiable subjects and relationships Which company, person, product, or concept is involved? Connecting a payroll platform with its company and features Topic clustering Organized coverage around connected questions Which supporting pages build subject depth? Connecting payroll guides and product pages A strong search strategy does not require choosing one approach and abandoning the others. Keyword research identifies demand, semantic coverage explains meaning, and entity SEO reduces ambiguity around the people, companies, products, and concepts represented. How Do Search Engines Recognize and Connect Entities? Search systems can build entity understanding from information gathered across webpages, structured databases, licensed sources, and other available resources. Google states that its Knowledge Graph maps attributes and relationships between real-world entities using information collected from several source types. A consistent entity name helps systems connect references that describe the same company, person, product, or service. A clear entity type distinguishes whether a name refers to an organization, person, place, product, event, or another subject. Relevant descriptive attributes provide context such as location, occupation, category, ownership, product type, or organizational role. Meaningful entity relationships connect companies with founders, products, locations, services, publications, partners, and other identifiable subjects. Supporting web references can provide corroborating information when credible sources describe the same entity using compatible facts and context. Structured machine-readable information can label entity details when suitable schema types and properties match the visible webpage content. No individual signal guarantees entity status or a search outcome. Search systems combine available information, relationships, and context when determining whether references describe the same subject. Which Signals Help Search Systems Understand a Brand Entity? Brand entity clarity improves when important information agrees across the places where search systems and users encounter the organization. Companies should concentrate on accurate identity, connected owned content, credible external corroboration, and understandable relationships rather than manufacturing large volumes of repetitive mentions. Consistent brand information: Company names, locations, service descriptions, leadership information, and important product names should remain consistent across key owned pages. Small wording variations are natural, although conflicting facts can create uncertainty around identity or current positioning. Clear About and profile pages: An About page should explain what the organization does, who it serves, where it operates, and whom or what it connects with. Founder and author profiles should also explain professional relationships rather than functioning as thin biography pages. Connected service and product information: Important offerings should connect with the organization through descriptive copy, navigation, internal links, and relevant structured data. This helps prevent products or services from appearing as isolated names without clear ownership, category, or business context. Relevant external references: Industry publications, professional profiles, partner websites, customer reviews, directories, interviews, and event pages can provide independent context. These sources are more valuable when they reflect real relationships rather than placements created solely to manufacture entity signals. Accurate structured data: Organization, Person, Product, ProfilePage, and related schema types can describe relevant page information when implemented correctly. Structured data gives search systems explicit clues about page meaning, while Google does not present schema as a guarantee of rankings. Our schema markup for AI search guide explains why structured data should support accurate page information instead of being treated as an
LLM Optimization (LLMO)
LLM optimization, or LLMO, improves how content and brand information can appear across LLM-powered search experiences. It focuses on what these systems can retrieve from the web and understand about a brand. The work also considers whether available sources provide enough context for accurate mentions, citations, comparisons, and generated answers. LLMO overlaps with SEO, AEO, and GEO, although each term emphasizes a different part of search visibility. The goal is not to manipulate a model or control what enters its training data. Instead, LLM optimization strengthens the discoverable information environment that can support accurate representation across relevant AI search experiences. Key Takeaways: LLM optimization improves how AI systems find and interpret brand information. LLMO overlaps with SEO, AEO, GEO, and wider AI search optimization. Live retrieval offers brands more control than training the underlying model. Strong LLM visibility depends on useful content and clear entities. External sources can shape how AI systems understand a brand. Technical accessibility remains important when AI search crawlers retrieve webpages. LLM optimization performance requires monitoring of prompts, citations, and representations. Why is LLM Optimization Crucial in AI Search? LLM optimization describes work that helps LLM-powered systems find, interpret, and represent useful information when responding to relevant prompts. The term often appears alongside LLM SEO, GEO, and AEO. There is no platform-defined LLMO standard, so definitions vary across search and marketing discussions. The core focus sits on the information environment available to an AI search experience. A model may answer based on learned information, retrieve current web sources, or combine both approaches, depending on the product and query. For brands, the more actionable layer is current web discovery. Search-enabled systems can retrieve pages and supporting sources when answering questions that require current information, comparisons, recommendations, or evidence. This means LLM optimization should focus on discoverable content instead of attempts to influence model weights. Search foundations, entity clarity, useful information, source credibility, and external references create a more defensible strategy. Readers unfamiliar with the underlying technology can first review our Large Language Model glossary before exploring the optimization layer in more depth. How Is LLM Optimization Different From SEO, GEO, and AEO? LLM optimization shares many foundations with other search disciplines, so treating every acronym as a separate strategy creates unnecessary complexity. Their main difference lies in the aspect of discovery each term emphasizes, rather than in a completely different set of content requirements. Term Main Focus Typical Outcome Core Question SEO Visibility across search engine results Rankings, impressions, clicks, conversions Can search engines discover and rank the page? AEO Selection within direct-answer experiences Answers, snippets, citations, mentions Can the content answer the question well? GEO Visibility within generated search responses Citations, mentions, recommendations Can generative systems use the brand as a source? LLMO Findability and representation across LLM-powered systems Accurate mentions, citations, comparisons Can LLM-based systems retrieve and understand the information? AI search optimization Broader visibility across AI-led discovery Cross-platform visibility and assisted discovery Is the brand discoverable across relevant AI search experiences? Google now states that standard SEO practices remain foundational for visibility across its generative Search experiences. Its guidance advises publishers to focus on useful content and sound technical foundations rather than on separate optimization shortcuts. This overlap means a company rarely needs four independent content programs. A stronger approach connects search foundations with Answer Engine Optimization, GEO, entity clarity, and LLM visibility measurement. Can Brands Optimize LLM Training Data and Live Retrieval the Same Way? Training and retrieval are often discussed together under LLM optimization, although businesses have different levels of influence over each layer. Current retrieval offers a more observable optimization surface because published information can become available without waiting for a future model training cycle. Training data influence: Model providers determine how training datasets are assembled, filtered, licensed, and processed for each model generation. Brands cannot assume that publishing a page guarantees training inclusion or controls how learned information will later appear in model responses. Pretrained model knowledge: An LLM can sometimes answer from information learned before deployment without retrieving a current webpage. That knowledge may become outdated when organizations change products, pricing, positioning, leadership, services, or other information after the model’s training period. Live web retrieval: Search-enabled AI experiences can find up-to-date web pages when a user asks questions requiring up-to-date information or supporting evidence. OpenAI states that public websites can appear in ChatGPT search when OAI-SearchBot can access eligible content, although placement is never guaranteed. Retrieval-augmented generation: RAG combines retrieved information with an LLM before an answer is generated. Retrieval-Augmented Generation (RAG) is a grounding technique that uses Search systems to retrieve relevant, up-to-date webpages for generative Search experiences. For this reason, brands gain more actionable opportunities from current content, crawl access, entity clarity, and source quality than speculative attempts to enter future training datasets. What Makes Content Easier for LLM Systems to Retrieve and Use? LLM optimization does not require a special writing formula that guarantees citations. Strong content still needs to answer genuine questions and provide information worth retrieving. Google now warns publishers against unnecessary AI-specific tactics, including forced content chunking designed around assumed generative search behavior. Cover the question with enough depth: A page should resolve the main query while answering the natural questions that follow. Useful examples, limitations, comparisons, definitions, and implementation details give retrieval systems more relevant information for different user intents. Make important facts easy to identify: Names, dates, products, services, definitions, pricing details, methodologies, and claims should appear in clear language. Readers and machines should not need several paragraphs of promotional copy before understanding the core information being communicated. Add evidence where claims require support: Original research, named sources, product documentation, methodologies, expert input, and verifiable examples make an explanation easier to evaluate. Unsupported statements weaken source material when an answer requires factual evidence or comparative context. Keep information current across key pages: Old service descriptions, pricing information, biographies, statistics, or feature details can create conflicts across a company’s website. Content audits should correct outdated information before
LLM optimization, or LLMO, improves how content and brand information can appear across LLM-powered search experiences. It focuses on what these systems can retrieve from the web and understand about a brand. The work also considers whether available sources provide enough context for accurate mentions, citations, comparisons, and generated answers. LLMO overlaps with SEO, AEO, and GEO, although each term emphasizes a different part of search visibility. The goal is not to manipulate a model or control what enters its training data. Instead, LLM optimization strengthens the discoverable information environment that can support accurate representation across relevant AI search experiences. Key Takeaways: LLM optimization improves how AI systems find and interpret brand information. LLMO overlaps with SEO, AEO, GEO, and wider AI search optimization. Live retrieval offers brands more control than training the underlying model. Strong LLM visibility depends on useful content and clear entities. External sources can shape how AI systems understand a brand. Technical accessibility remains important when AI search crawlers retrieve webpages. LLM optimization performance requires monitoring of prompts, citations, and representations. Why is LLM Optimization Crucial in AI Search? LLM optimization describes work that helps LLM-powered systems find, interpret, and represent useful information when responding to relevant prompts. The term often appears alongside LLM SEO, GEO, and AEO. There is no platform-defined LLMO standard, so definitions vary across search and marketing discussions. The core focus sits on the information environment available to an AI search experience. A model may answer based on learned information, retrieve current web sources, or combine both approaches, depending on the product and query. For brands, the more actionable layer is current web discovery. Search-enabled systems can retrieve pages and supporting sources when answering questions that require current information, comparisons, recommendations, or evidence. This means LLM optimization should focus on discoverable content instead of attempts to influence model weights. Search foundations, entity clarity, useful information, source credibility, and external references create a more defensible strategy. Readers unfamiliar with the underlying technology can first review our Large Language Model glossary before exploring the optimization layer in more depth. How Is LLM Optimization Different From SEO, GEO, and AEO? LLM optimization shares many foundations with other search disciplines, so treating every acronym as a separate strategy creates unnecessary complexity. Their main difference lies in the aspect of discovery each term emphasizes, rather than in a completely different set of content requirements. Term Main Focus Typical Outcome Core Question SEO Visibility across search engine results Rankings, impressions, clicks, conversions Can search engines discover and rank the page? AEO Selection within direct-answer experiences Answers, snippets, citations, mentions Can the content answer the question well? GEO Visibility within generated search responses Citations, mentions, recommendations Can generative systems use the brand as a source? LLMO Findability and representation across LLM-powered systems Accurate mentions, citations, comparisons Can LLM-based systems retrieve and understand the information? AI search optimization Broader visibility across AI-led discovery Cross-platform visibility and assisted discovery Is the brand discoverable across relevant AI search experiences? Google now states that standard SEO practices remain foundational for visibility across its generative Search experiences. Its guidance advises publishers to focus on useful content and sound technical foundations rather than on separate optimization shortcuts. This overlap means a company rarely needs four independent content programs. A stronger approach connects search foundations with Answer Engine Optimization, GEO, entity clarity, and LLM visibility measurement. Can Brands Optimize LLM Training Data and Live Retrieval the Same Way? Training and retrieval are often discussed together under LLM optimization, although businesses have different levels of influence over each layer. Current retrieval offers a more observable optimization surface because published information can become available without waiting for a future model training cycle. Training data influence: Model providers determine how training datasets are assembled, filtered, licensed, and processed for each model generation. Brands cannot assume that publishing a page guarantees training inclusion or controls how learned information will later appear in model responses. Pretrained model knowledge: An LLM can sometimes answer from information learned before deployment without retrieving a current webpage. That knowledge may become outdated when organizations change products, pricing, positioning, leadership, services, or other information after the model’s training period. Live web retrieval: Search-enabled AI experiences can find up-to-date web pages when a user asks questions requiring up-to-date information or supporting evidence. OpenAI states that public websites can appear in ChatGPT search when OAI-SearchBot can access eligible content, although placement is never guaranteed. Retrieval-augmented generation: RAG combines retrieved information with an LLM before an answer is generated. Retrieval-Augmented Generation (RAG) is a grounding technique that uses Search systems to retrieve relevant, up-to-date webpages for generative Search experiences. For this reason, brands gain more actionable opportunities from current content, crawl access, entity clarity, and source quality than speculative attempts to enter future training datasets. What Makes Content Easier for LLM Systems to Retrieve and Use? LLM optimization does not require a special writing formula that guarantees citations. Strong content still needs to answer genuine questions and provide information worth retrieving. Google now warns publishers against unnecessary AI-specific tactics, including forced content chunking designed around assumed generative search behavior. Cover the question with enough depth: A page should resolve the main query while answering the natural questions that follow. Useful examples, limitations, comparisons, definitions, and implementation details give retrieval systems more relevant information for different user intents. Make important facts easy to identify: Names, dates, products, services, definitions, pricing details, methodologies, and claims should appear in clear language. Readers and machines should not need several paragraphs of promotional copy before understanding the core information being communicated. Add evidence where claims require support: Original research, named sources, product documentation, methodologies, expert input, and verifiable examples make an explanation easier to evaluate. Unsupported statements weaken source material when an answer requires factual evidence or comparative context. Keep information current across key pages: Old service descriptions, pricing information, biographies, statistics, or feature details can create conflicts across a company’s website. Content audits should correct outdated information before
Schema Markup
Schema markup is machine-readable code that helps search engines understand what a webpage contains and what its information represents. It can identify articles, products, organizations, people, events, reviews, and other entities in a consistent format. This added context can support richer search appearances when systems recognize and use the markup. However, schema markup does not guarantee higher rankings, AI citations, or inclusion in Google AI Overviews. Its main role is to make page information easier for machines to interpret across search experiences. Used correctly, it strengthens technical clarity while supporting SEO, AEO, and GEO efforts built around useful, well-structured content. Key Takeaways Schema markup gives search systems clearer labels for important webpage information. Schema.org provides the vocabulary for describing entities and page content. Google supports JSON-LD, Microdata, and RDFa for structured data implementation. JSON-LD is preferred because teams can maintain the format with less effort. A valid schema can create eligibility for rich results without guaranteeing their appearance. Schema markup is not a direct shortcut to higher organic rankings. Google does not require special schema for AI Overviews or AI Mode. What Is Schema Markup and How Does It Work? Schema markup adds standardized labels to information that people can already understand from visible webpage content. A product page may show a name, price, brand, availability, and review score. Schema connects those details with machine-readable properties that explain what each value represents. Search engines can then use those labels when processing the page and deciding whether supported search features apply. Google describes structured data as a standardized format for classifying page information, while most Search implementations use Schema.org vocabulary. The markup should describe the same information that is visible to readers, rather than creating a second version of the page. Accurate implementation enhances clarity, while misleading or hidden information can render a page ineligible for rich-results features under Google guidelines. How Is Schema Markup Different From Structured Data and Schema.org? These terms appear together so often that they can sound interchangeable, although each describes a different part of the system. The difference helps content teams discuss requirements with SEO specialists and developers without treating each technical layer as the same thing. Term What It Means Simple Example Main Role Structured data Information organized in a standard machine-readable format A product price identified as a price Gives machines labeled information Schema.org A shared vocabulary containing types and properties Product, Person, Organization Defines what labels mean Schema markup Schema.org vocabulary added to webpage code Product details expressed through JSON-LD Applies structured meaning to a page JSON-LD One supported format for writing structured data A script containing @type and properties Provides an implementation method Google supports JSON-LD, Microdata, and RDFa for Search structured data, while Schema.org provides a much wider vocabulary. Teams should therefore check Google documentation before expecting every valid Schema.org type to create a supported Search feature. Which Schema Markup Types Should a Website Use? A website should use schema types that match each page’s actual purpose and visible content, rather than adding unrelated markup. Teams should start with important page templates, identify the entities or content being described, and select supported types that fit those pages. Organization: Organization markup can describe a company name, logo, URL, address, contact details, and related information when applicable. Google recommends placing organizational information on the home page or on another page that describes the organization to reduce conflicting details across templates. Article: Article markup identifies information such as the headline, images, publication dates, and author details. Publishers can use it on suitable article pages when the marked information matches the visible byline, publication date, main image, and page content. Product: Product structured data can describe price, availability, ratings, shipping details, and other product attributes shown on a page. Google separates product snippets from merchant listings because direct-purchase pages may require different information than editorial pages that review products. LocalBusiness: LocalBusiness markup can describe a physical business location through information such as its address, telephone number, opening hours, and business subtype. The chosen subtype should align with the business represented on the page, and the markup should match the visible location information. Breadcrumb: Breadcrumb structured data describes a page’s position within the website hierarchy and the path leading toward it. Google can use this information in supported Search appearances to show how deeper pages connect with broader categories and website sections. A SaaS website may emphasize Organization, Article, Breadcrumb, and SoftwareApplication information, while ecommerce sites may require Product markup across catalogs. How Do You Add and Validate Schema Markup? Adding schema markup is not limited to generating code and pasting it into a page template. The markup should match visible content, use the correct type, contain required properties, pass validation, and remain accurate after website changes. Choose the page purpose first: Teams should identify what the page represents before selecting markup for its content. A home page, article, product page, author profile, event page, and location page describe different entities that can require different supported schema types. Select an implementation format: Google supports three structured data implementation formats for Search: JSON-LD, Microdata, and RDFa. Google recommends JSON-LD in most situations because teams can maintain it without placing every property throughout visible HTML, although the chosen format should fit the website setup. Map visible information to properties: Required and recommended properties should describe information readers can verify on the page. A product price in markup should match the displayed price, while an article author should match the person shown to readers and the published byline. Validate before deployment: Google’s Rich Results Test checks whether page markup supports eligible Google Search features. The Schema Markup Validator checks broader Schema.org markup for general vocabulary errors. This separates general vocabulary validity from Google-specific rich-result eligibility during implementation reviews. Monitor after publishing: A valid implementation can break when templates, plugins, prices, business details, or page layouts change. Search Console enhancement reports, URL Inspection, and recurring technical reviews can identify stale, broken, or conflicting structured information across
Schema markup is machine-readable code that helps search engines understand what a webpage contains and what its information represents. It can identify articles, products, organizations, people, events, reviews, and other entities in a consistent format. This added context can support richer search appearances when systems recognize and use the markup. However, schema markup does not guarantee higher rankings, AI citations, or inclusion in Google AI Overviews. Its main role is to make page information easier for machines to interpret across search experiences. Used correctly, it strengthens technical clarity while supporting SEO, AEO, and GEO efforts built around useful, well-structured content. Key Takeaways Schema markup gives search systems clearer labels for important webpage information. Schema.org provides the vocabulary for describing entities and page content. Google supports JSON-LD, Microdata, and RDFa for structured data implementation. JSON-LD is preferred because teams can maintain the format with less effort. A valid schema can create eligibility for rich results without guaranteeing their appearance. Schema markup is not a direct shortcut to higher organic rankings. Google does not require special schema for AI Overviews or AI Mode. What Is Schema Markup and How Does It Work? Schema markup adds standardized labels to information that people can already understand from visible webpage content. A product page may show a name, price, brand, availability, and review score. Schema connects those details with machine-readable properties that explain what each value represents. Search engines can then use those labels when processing the page and deciding whether supported search features apply. Google describes structured data as a standardized format for classifying page information, while most Search implementations use Schema.org vocabulary. The markup should describe the same information that is visible to readers, rather than creating a second version of the page. Accurate implementation enhances clarity, while misleading or hidden information can render a page ineligible for rich-results features under Google guidelines. How Is Schema Markup Different From Structured Data and Schema.org? These terms appear together so often that they can sound interchangeable, although each describes a different part of the system. The difference helps content teams discuss requirements with SEO specialists and developers without treating each technical layer as the same thing. Term What It Means Simple Example Main Role Structured data Information organized in a standard machine-readable format A product price identified as a price Gives machines labeled information Schema.org A shared vocabulary containing types and properties Product, Person, Organization Defines what labels mean Schema markup Schema.org vocabulary added to webpage code Product details expressed through JSON-LD Applies structured meaning to a page JSON-LD One supported format for writing structured data A script containing @type and properties Provides an implementation method Google supports JSON-LD, Microdata, and RDFa for Search structured data, while Schema.org provides a much wider vocabulary. Teams should therefore check Google documentation before expecting every valid Schema.org type to create a supported Search feature. Which Schema Markup Types Should a Website Use? A website should use schema types that match each page’s actual purpose and visible content, rather than adding unrelated markup. Teams should start with important page templates, identify the entities or content being described, and select supported types that fit those pages. Organization: Organization markup can describe a company name, logo, URL, address, contact details, and related information when applicable. Google recommends placing organizational information on the home page or on another page that describes the organization to reduce conflicting details across templates. Article: Article markup identifies information such as the headline, images, publication dates, and author details. Publishers can use it on suitable article pages when the marked information matches the visible byline, publication date, main image, and page content. Product: Product structured data can describe price, availability, ratings, shipping details, and other product attributes shown on a page. Google separates product snippets from merchant listings because direct-purchase pages may require different information than editorial pages that review products. LocalBusiness: LocalBusiness markup can describe a physical business location through information such as its address, telephone number, opening hours, and business subtype. The chosen subtype should align with the business represented on the page, and the markup should match the visible location information. Breadcrumb: Breadcrumb structured data describes a page’s position within the website hierarchy and the path leading toward it. Google can use this information in supported Search appearances to show how deeper pages connect with broader categories and website sections. A SaaS website may emphasize Organization, Article, Breadcrumb, and SoftwareApplication information, while ecommerce sites may require Product markup across catalogs. How Do You Add and Validate Schema Markup? Adding schema markup is not limited to generating code and pasting it into a page template. The markup should match visible content, use the correct type, contain required properties, pass validation, and remain accurate after website changes. Choose the page purpose first: Teams should identify what the page represents before selecting markup for its content. A home page, article, product page, author profile, event page, and location page describe different entities that can require different supported schema types. Select an implementation format: Google supports three structured data implementation formats for Search: JSON-LD, Microdata, and RDFa. Google recommends JSON-LD in most situations because teams can maintain it without placing every property throughout visible HTML, although the chosen format should fit the website setup. Map visible information to properties: Required and recommended properties should describe information readers can verify on the page. A product price in markup should match the displayed price, while an article author should match the person shown to readers and the published byline. Validate before deployment: Google’s Rich Results Test checks whether page markup supports eligible Google Search features. The Schema Markup Validator checks broader Schema.org markup for general vocabulary errors. This separates general vocabulary validity from Google-specific rich-result eligibility during implementation reviews. Monitor after publishing: A valid implementation can break when templates, plugins, prices, business details, or page layouts change. Search Console enhancement reports, URL Inspection, and recurring technical reviews can identify stale, broken, or conflicting structured information across
How Can GEO for Local Business Improve Multi-Location AI Visibility?
A customer looking for a nearby business no longer needs to search with a short phrase. They can ask for an accountant experienced with startups near Indiranagar or a dentist who is open on Saturdays with strong recent reviews. AI search can interpret several conditions before suggesting businesses. This trend redefines the importance of GEO for local business. Visibility now depends on whether search systems can connect a company with the right location and service. Accurate business information and useful local evidence become important parts of that matching process. Multi-location businesses face an additional challenge. Every branch needs sufficient distinct information to accurately represent its location without fragmenting the wider brand. This blog explains how local businesses can build that information system and measure whether AI-led discovery improves. Key Takeaways Local GEO depends on accurate location facts across every public business source. AI recommendations today combine local relevance with reviews and broader web evidence. Google Business Profiles remain essential inputs for Search and Maps discovery today. Multi-location brands need unique pages without duplicating generic location template content everywhere. Reviews strengthen local trust when they stay recent and location-specific consistently over time. Service-area clarity helps AI systems match businesses to geographically specific customer needs. Local GEO measurement consistently requires repeated prompts across locations and commercial scenarios. Central governance prevents profile inconsistencies from quickly multiplying across large location networks. What Is GEO for Local Business? GEO for local business improves how a company appears inside AI-generated recommendations tied to a geographic need. It connects accurate location information with useful website content and credible external evidence. The goal is to help AI systems understand which location best fits a specific customer question and why. Traditional local SEO remains the foundation. Google still uses local information to match businesses with nearby users across Search and Maps. GEO adds another layer, allowing people to describe complete situations rather than entering short service-plus-city keywords. For example, a user may ask for a coworking space near Koramangala that supports day passes and late-evening access. Another may ask which physiotherapy clinic near Powai specializes in sports rehabilitation and has weekend appointments. Those prompts require more than basic category relevance. Scribblers India’s Generative Engine Optimization services examine this wider discovery environment. Local GEO narrows that work around geographic relevance and location-level accuracy while keeping the brand understandable across every branch. This distinction becomes more important as local discovery begins to span several search experiences. Why Does AI Search Matter for Local Businesses in 2026? AI search matters because consumers increasingly use AI tools in their local business research. Google has also integrated conversational AI directly into Search and Maps-related journeys. Local businesses therefore need accurate information across the sources people use before they decide which company deserves further consideration. An industry study found that 84% of consumers searched online for a local business in the previous three months, according to its 2026 research. The same study found AI tools appeared during 23% of consumers’ most recent local search journeys. Google’s behavior is changing as well. AI Mode supports complex local recommendation questions, while Google says early AI Mode queries were two to three times longer than traditional searches. Longer prompts create more opportunities for customers to specify location and service needs together. The implication of GEO for local businesses is functional: brands now compete in richer recommendation contexts, where incomplete information can remove them before a customer reaches their website. How Do AI Search Systems Find Information About Local Businesses? AI search systems can combine official business information with website content and wider public sources. Google explicitly states that Local Business Profiles draw information from business owners and public web content. Licensed third-party data and user contributions can provide additional details about real-world businesses. Google explains that its Business Profiles may combine company-submitted details with information from official websites and external providers. Customer photos or reviews can also contribute to the profile users eventually see. ChatGPT can also use location information when answering requests that benefit from local results. OpenAI states that ChatGPT search can find local results and use location context where available. It may use third-party providers to help return relevant nearby information. This creates an important GEO principle. Your website is one source within a wider local information environment rather than the only source defining the business. A strong GEO strategy for local business must therefore make the same essential facts understandable across owned pages and important public profiles. Once those facts align, content can provide the additional evidence needed for recommendation. How Is GEO for Local Business Different From Traditional Local SEO? Local SEO improves visibility across geographically relevant Search and Maps results, while GEO adds AI-generated recommendations and conversational discovery. The two approaches share important foundations. GEO for local business places additional emphasis on detailed prompt matching, information consistency, recommendation context, external evidence, and location-level measurement across generative experiences. Google says conventional local results mainly depend on relevance and distance, with prominence providing another major factor. Complete Business Profile information helps Google understand how closely a business matches what someone needs. Reviews and links can contribute to prominence. GEO for local business builds on those fundamentals rather than replacing them. Local SEO Focus GEO for Local Business Focus Local pack and Maps rankings Inclusion inside AI-generated recommendations Service plus location queries Detailed conversational local questions Google Business Profile optimization Cross-source location understanding Local landing-page rankings Location-level answer and recommendation readiness Review quantity and rating Review themes, recency, and recommendation evidence Organic calls and visits AI mentions, referrals, and assisted actions The strongest strategy therefore avoids choosing between local SEO and GEO. Businesses need a reliable local search foundation before expecting generative platforms to interpret their locations consistently. Which Signals Matter Most for Local AI Search Visibility? Local AI search visibility depends on a connected set of signals rather than on a single optimization tactic. Accurate Business Profiles establish core facts, while location pages explain individual branches. Reviews and
A customer looking for a nearby business no longer needs to search with a short phrase. They can ask for an accountant experienced with startups near Indiranagar or a dentist who is open on Saturdays with strong recent reviews. AI search can interpret several conditions before suggesting businesses. This trend redefines the importance of GEO for local business. Visibility now depends on whether search systems can connect a company with the right location and service. Accurate business information and useful local evidence become important parts of that matching process. Multi-location businesses face an additional challenge. Every branch needs sufficient distinct information to accurately represent its location without fragmenting the wider brand. This blog explains how local businesses can build that information system and measure whether AI-led discovery improves. Key Takeaways Local GEO depends on accurate location facts across every public business source. AI recommendations today combine local relevance with reviews and broader web evidence. Google Business Profiles remain essential inputs for Search and Maps discovery today. Multi-location brands need unique pages without duplicating generic location template content everywhere. Reviews strengthen local trust when they stay recent and location-specific consistently over time. Service-area clarity helps AI systems match businesses to geographically specific customer needs. Local GEO measurement consistently requires repeated prompts across locations and commercial scenarios. Central governance prevents profile inconsistencies from quickly multiplying across large location networks. What Is GEO for Local Business? GEO for local business improves how a company appears inside AI-generated recommendations tied to a geographic need. It connects accurate location information with useful website content and credible external evidence. The goal is to help AI systems understand which location best fits a specific customer question and why. Traditional local SEO remains the foundation. Google still uses local information to match businesses with nearby users across Search and Maps. GEO adds another layer, allowing people to describe complete situations rather than entering short service-plus-city keywords. For example, a user may ask for a coworking space near Koramangala that supports day passes and late-evening access. Another may ask which physiotherapy clinic near Powai specializes in sports rehabilitation and has weekend appointments. Those prompts require more than basic category relevance. Scribblers India’s Generative Engine Optimization services examine this wider discovery environment. Local GEO narrows that work around geographic relevance and location-level accuracy while keeping the brand understandable across every branch. This distinction becomes more important as local discovery begins to span several search experiences. Why Does AI Search Matter for Local Businesses in 2026? AI search matters because consumers increasingly use AI tools in their local business research. Google has also integrated conversational AI directly into Search and Maps-related journeys. Local businesses therefore need accurate information across the sources people use before they decide which company deserves further consideration. An industry study found that 84% of consumers searched online for a local business in the previous three months, according to its 2026 research. The same study found AI tools appeared during 23% of consumers’ most recent local search journeys. Google’s behavior is changing as well. AI Mode supports complex local recommendation questions, while Google says early AI Mode queries were two to three times longer than traditional searches. Longer prompts create more opportunities for customers to specify location and service needs together. The implication of GEO for local businesses is functional: brands now compete in richer recommendation contexts, where incomplete information can remove them before a customer reaches their website. How Do AI Search Systems Find Information About Local Businesses? AI search systems can combine official business information with website content and wider public sources. Google explicitly states that Local Business Profiles draw information from business owners and public web content. Licensed third-party data and user contributions can provide additional details about real-world businesses. Google explains that its Business Profiles may combine company-submitted details with information from official websites and external providers. Customer photos or reviews can also contribute to the profile users eventually see. ChatGPT can also use location information when answering requests that benefit from local results. OpenAI states that ChatGPT search can find local results and use location context where available. It may use third-party providers to help return relevant nearby information. This creates an important GEO principle. Your website is one source within a wider local information environment rather than the only source defining the business. A strong GEO strategy for local business must therefore make the same essential facts understandable across owned pages and important public profiles. Once those facts align, content can provide the additional evidence needed for recommendation. How Is GEO for Local Business Different From Traditional Local SEO? Local SEO improves visibility across geographically relevant Search and Maps results, while GEO adds AI-generated recommendations and conversational discovery. The two approaches share important foundations. GEO for local business places additional emphasis on detailed prompt matching, information consistency, recommendation context, external evidence, and location-level measurement across generative experiences. Google says conventional local results mainly depend on relevance and distance, with prominence providing another major factor. Complete Business Profile information helps Google understand how closely a business matches what someone needs. Reviews and links can contribute to prominence. GEO for local business builds on those fundamentals rather than replacing them. Local SEO Focus GEO for Local Business Focus Local pack and Maps rankings Inclusion inside AI-generated recommendations Service plus location queries Detailed conversational local questions Google Business Profile optimization Cross-source location understanding Local landing-page rankings Location-level answer and recommendation readiness Review quantity and rating Review themes, recency, and recommendation evidence Organic calls and visits AI mentions, referrals, and assisted actions The strongest strategy therefore avoids choosing between local SEO and GEO. Businesses need a reliable local search foundation before expecting generative platforms to interpret their locations consistently. Which Signals Matter Most for Local AI Search Visibility? Local AI search visibility depends on a connected set of signals rather than on a single optimization tactic. Accurate Business Profiles establish core facts, while location pages explain individual branches. Reviews and
Does Schema Markup Help AI Search Visibility in 2026?
Schema markup for AI search has acquired a new reputation since generative search entered mainstream marketing discussions. Some advice now presents structured data as a direct route into ChatGPT responses or Google AI Overviews. Other recommendations suggest creating an extensive “GEO schema” layer before addressing weak website content. The evidence does not support that interpretation. Schema markup for AI search can still serve useful technical purposes, yet current Google guidance does not treat it as a generative ranking requirement. Recent independent testing also fails to show a clear increase in citations from adding JSON-LD alone. That distinction changes how businesses should prioritize technical work. Schema remains part of a healthy search foundation, while greater AI visibility depends on a broader information ecosystem. Brands need accurate entities, useful answers, credible evidence, sound search access, and content that deserves retrieval. Key Takeaways Schema markup for AI search helps machines classify information but does not guarantee AI citations. Google says generative Search requires no special structured data or schema. Recent testing found no meaningful uplift in citations after adding JSON-LD markup. Structured data still supports rich results and clearer entity information today. Product and local schemas remain useful where structured facts affect discovery. Schema works best when visible content already provides complete, trustworthy answers. Brands should fix weak content before expanding large structured data implementations. Measure the schema against defined outcomes rather than assuming automatic GEO benefits. Does Schema Markup Directly Improve AI Search Visibility? Schema markup for AI search does not currently have proven direct impact on citation visibility. Google explicitly says structured data is not required for generative AI Search. Independent 2026 testing also found no meaningful increase in citations after pages added JSON-LD in Google AI Mode or ChatGPT. This conclusion differs from a common marketing claim that schema automatically makes content easier for large language models to cite. Structured data can provide machine-readable context, yet that technical function should not be confused with a confirmed citation-ranking signal. A 2026 industry study tracked 1,885 pages that added JSON-LD between August 2025 and March 2026. The researchers matched those pages against control URLs and measured citation changes across AI Overviews, AI Mode, and ChatGPT. No clear positive citation effect appeared. Google reaches the same practical conclusion from a platform perspective. Its current generative search guidance says there is no special Schema.org markup that websites must add for AI Overviews or AI Mode. The crucial question is therefore not whether Schema markup for AI search is “good” or “bad.” Businesses need to understand what it genuinely does before deciding how much effort it deserves. How Does Structured Data Help Search Engines? Structured data provides standardized information that helps search engines classify page content and specific entities. It can support rich-result eligibility and clarify facts about products or organizations. Its established value lies mainly in search understanding and search presentation, rather than in guaranteed visibility for generative citations. Schema.org provides the vocabulary, while formats such as JSON-LD carry that vocabulary inside webpages. A search engine can use the markup to identify an author, product, organization, location, rating, price, event, or another supported entity. Google explains that structured data provides explicit clues about a page and can make eligible content available for richer search experiences. Google currently recommends JSON-LD for many implementations because teams can usually maintain it more easily. That function remains useful even when schema does not create an independent AI-ranking advantage. A product page with accurate Product markup can support search features. An organization page can provide clearer administrative details. This distinction creates the first practical rule: implement schema for supported information and search functions, not as an isolated shortcut into generative answers. Why Do So Many AI-Cited Pages Still Use Schema Markup? AI-cited pages frequently use schema because well-maintained websites often invest in several search fundamentals together. Those sites may publish stronger content and maintain cleaner technical infrastructure. Schema markup for AI search can therefore correlate with AI visibility without causing the visibility that marketers observe. The difference between correlation and causation is especially important here. Ahrefs first analyzed 6 million URLs and found that schema markup for AI search was substantially more common among pages receiving AI citations. In that dataset, 53% of AI-cited pages used schema markup. This observation could easily support the wrong conclusion. Websites that use structured data often invest in content quality, page maintenance, internal linking, authority development, and stronger conventional SEO. Ahrefs therefore ran a second analysis designed to isolate the schema change. The citation advantage largely disappeared when pages adding JSON-LD were compared with matched controls. Observation Easy Conclusion Better Interpretation Cited pages often contain schema Schema causes citations Strong websites often use schema JSON-LD is common on authoritative sites AI systems reward JSON-LD Technical maturity may correlate with authority Schema pages earn rich results Schema improves all search visibility Rich-result eligibility is a separate outcome Adding schema changes machine-readable data Citations should increase automatically Retrieval still depends on wider signals This is why the broader Scribblers India AI Search Discovery Benchmark evaluates AI readiness across multiple information signals instead of assigning schema disproportionate weight. Does Google Require Schema markup for AI search for AI Mode or Overviews? Google does not require structured data for AI Overviews or AI Mode. Its 2026 guidance explicitly states that generative search requires no special schema markup for AI search. Google recommends continuing normal structured data practices where they support conventional Search features, while keeping established SEO fundamentals in place. This clarification addresses one of the biggest misconceptions around structured data for AI search. Google’s generative features rely on its Search index and core ranking systems rather than a separate schema-driven submission process. A valid schema implementation, therefore, does not automatically make a page eligible for citation in an AI Overview. The page still needs to be accessible and relevant. Its visible content must also provide information worth retrieving in response to the query. The same logic applies to elaborate
Schema markup for AI search has acquired a new reputation since generative search entered mainstream marketing discussions. Some advice now presents structured data as a direct route into ChatGPT responses or Google AI Overviews. Other recommendations suggest creating an extensive “GEO schema” layer before addressing weak website content. The evidence does not support that interpretation. Schema markup for AI search can still serve useful technical purposes, yet current Google guidance does not treat it as a generative ranking requirement. Recent independent testing also fails to show a clear increase in citations from adding JSON-LD alone. That distinction changes how businesses should prioritize technical work. Schema remains part of a healthy search foundation, while greater AI visibility depends on a broader information ecosystem. Brands need accurate entities, useful answers, credible evidence, sound search access, and content that deserves retrieval. Key Takeaways Schema markup for AI search helps machines classify information but does not guarantee AI citations. Google says generative Search requires no special structured data or schema. Recent testing found no meaningful uplift in citations after adding JSON-LD markup. Structured data still supports rich results and clearer entity information today. Product and local schemas remain useful where structured facts affect discovery. Schema works best when visible content already provides complete, trustworthy answers. Brands should fix weak content before expanding large structured data implementations. Measure the schema against defined outcomes rather than assuming automatic GEO benefits. Does Schema Markup Directly Improve AI Search Visibility? Schema markup for AI search does not currently have proven direct impact on citation visibility. Google explicitly says structured data is not required for generative AI Search. Independent 2026 testing also found no meaningful increase in citations after pages added JSON-LD in Google AI Mode or ChatGPT. This conclusion differs from a common marketing claim that schema automatically makes content easier for large language models to cite. Structured data can provide machine-readable context, yet that technical function should not be confused with a confirmed citation-ranking signal. A 2026 industry study tracked 1,885 pages that added JSON-LD between August 2025 and March 2026. The researchers matched those pages against control URLs and measured citation changes across AI Overviews, AI Mode, and ChatGPT. No clear positive citation effect appeared. Google reaches the same practical conclusion from a platform perspective. Its current generative search guidance says there is no special Schema.org markup that websites must add for AI Overviews or AI Mode. The crucial question is therefore not whether Schema markup for AI search is “good” or “bad.” Businesses need to understand what it genuinely does before deciding how much effort it deserves. How Does Structured Data Help Search Engines? Structured data provides standardized information that helps search engines classify page content and specific entities. It can support rich-result eligibility and clarify facts about products or organizations. Its established value lies mainly in search understanding and search presentation, rather than in guaranteed visibility for generative citations. Schema.org provides the vocabulary, while formats such as JSON-LD carry that vocabulary inside webpages. A search engine can use the markup to identify an author, product, organization, location, rating, price, event, or another supported entity. Google explains that structured data provides explicit clues about a page and can make eligible content available for richer search experiences. Google currently recommends JSON-LD for many implementations because teams can usually maintain it more easily. That function remains useful even when schema does not create an independent AI-ranking advantage. A product page with accurate Product markup can support search features. An organization page can provide clearer administrative details. This distinction creates the first practical rule: implement schema for supported information and search functions, not as an isolated shortcut into generative answers. Why Do So Many AI-Cited Pages Still Use Schema Markup? AI-cited pages frequently use schema because well-maintained websites often invest in several search fundamentals together. Those sites may publish stronger content and maintain cleaner technical infrastructure. Schema markup for AI search can therefore correlate with AI visibility without causing the visibility that marketers observe. The difference between correlation and causation is especially important here. Ahrefs first analyzed 6 million URLs and found that schema markup for AI search was substantially more common among pages receiving AI citations. In that dataset, 53% of AI-cited pages used schema markup. This observation could easily support the wrong conclusion. Websites that use structured data often invest in content quality, page maintenance, internal linking, authority development, and stronger conventional SEO. Ahrefs therefore ran a second analysis designed to isolate the schema change. The citation advantage largely disappeared when pages adding JSON-LD were compared with matched controls. Observation Easy Conclusion Better Interpretation Cited pages often contain schema Schema causes citations Strong websites often use schema JSON-LD is common on authoritative sites AI systems reward JSON-LD Technical maturity may correlate with authority Schema pages earn rich results Schema improves all search visibility Rich-result eligibility is a separate outcome Adding schema changes machine-readable data Citations should increase automatically Retrieval still depends on wider signals This is why the broader Scribblers India AI Search Discovery Benchmark evaluates AI readiness across multiple information signals instead of assigning schema disproportionate weight. Does Google Require Schema markup for AI search for AI Mode or Overviews? Google does not require structured data for AI Overviews or AI Mode. Its 2026 guidance explicitly states that generative search requires no special schema markup for AI search. Google recommends continuing normal structured data practices where they support conventional Search features, while keeping established SEO fundamentals in place. This clarification addresses one of the biggest misconceptions around structured data for AI search. Google’s generative features rely on its Search index and core ranking systems rather than a separate schema-driven submission process. A valid schema implementation, therefore, does not automatically make a page eligible for citation in an AI Overview. The page still needs to be accessible and relevant. Its visible content must also provide information worth retrieving in response to the query. The same logic applies to elaborate
What are GEO services cost in India for 2026?
Finding a reliable answer for GEO services cost in India has become difficult because agencies package very different work under the same label. One provider may offer prompt tracking and basic technical checks. Another may combine research, content development, authority building, page optimization, and ongoing visibility measurement. That difference explains why published prices can range from a few thousand rupees for basic audits to several lakh rupees monthly. Comparing those numbers without understanding their scope can therefore create a misleading view of the actual market. Businesses need a better pricing framework. The right question is not simply, “How much do GEO services cost in India?” The more useful question asks what level of GEO work your current visibility gaps require. Key Takeaways GEO retainers in India vary widely because the scope of services differs among providers. A serious GEO audit should diagnose visibility gaps before recommending monthly execution. Monthly GEO pricing rises with content depth and broader cross-platform measurement complexity. Cheap packages often cover monitoring while larger retainers fund ongoing implementation work. Google requires no special AI markup for AI Overview or Mode visibility. Brands should compare deliverables and ownership before judging the prices of competing GEO agencies. Strong SEO foundations still support generative visibility across Google AI experiences today. GEO performance requires repeatable prompts, along with source and business outcome measurement. How Much Do GEO Services Cost in India in 2026? GEO services in India can cost around ₹15,000–₹60,000 for a substantive one-time audit. Focused monthly programs often start near ₹35,000–₹80,000. Broader growth retainers may reach ₹75,000–₹1.5 lakh, while scaled programs can exceed ₹1.5–₹3.5 lakh monthly. These ranges for GEO services cost in India should be treated as planning benchmarks rather than fixed industry prices. Publicly listed Indian offers currently show monthly pricing starting around ₹18,000, ₹35,000, and ₹40,000 across different providers. Other published GEO pricing frameworks set higher retainers at ₹1.5 lakh per month or above. The table below normalizes those public offers by the likely depth of engagement. Engagement Type Indicative 2026 Budget Typical Scope Suitable For Focused GEO audit ₹15,000–₹60,000 one-time Visibility baseline, prompt testing, competitor review, prioritized roadmap First-time GEO buyers Focused retainer ₹35,000–₹80,000 monthly Priority prompts, key-page updates, basic tracking, limited new content Smaller brands Growth program ₹75,000–₹1.5 lakh monthly Content creation, refreshes, competitor tracking, deeper source analysis Growing B2B brands Scaled GEO program ₹1.5–₹3.5 lakh+ monthly Larger topic coverage, authority assets, cross-platform measurement, deeper execution Competitive categories Enterprise engagement ₹3 lakh+ monthly Multiple markets, complex portfolios, extensive authority work, dedicated reporting Larger organizations UpGrowth, for example, places Indian mid-market GEO and AEO retainers at ₹75,000 to ₹3.5 lakh per month. Other providers publish lower starting rates because their entry packages cover narrower workloads. This range makes one point clear. Price begins making sense only after you understand exactly what the agency intends to deliver. What Does GEO Services Cost in India Cover? GEO agency pricing should fund work that changes how your brand is understood and represented across generative discovery. That normally includes diagnosis and execution. A useful engagement should not be limited to improving the owned content and external information sources that influence important buyer questions. Understanding this distinction becomes easier after reviewing what generative engine optimization services involve. GEO examines buyer prompts, competing brands, relevant sources, content gaps, entity accuracy, and measurable representation across selected platforms. A robust GEO engagement in India generally covers several connected workstreams: Buyer Prompt Research: Commercially relevant prompts should reflect how buyers research problems and evaluate providers. The agency should separate high-value questions from broad informational queries. This keeps tracking connected with actual business priorities rather than producing an impressive prompt count with limited commercial value. Visibility Baseline: Initial testing should document where the brand appears across agreed AI experiences. It should also record competitor presence, citations where available, and answer context. These observations create the controlled baseline needed for later comparisons after content or authority improvements. Content Gap Mapping: Existing pages should be reviewed against the questions AI systems and buyers need answered. Scribblers India explains this process further in its AI content gap analysis framework, which identifies missing answers, weak evidence, and incomplete content coverage. Content Execution: GEO programs often require existing pages to be refreshed or new assets created. The scope may include comparison pages, expert guides, original research, case-led resources, service content, or commercially focused articles designed around verified information gaps. Measurement Cycles: Priority prompts must be tested again under comparable conditions after implementation. A useful report should show changes in brand representation and competitor presence. It should also connect those observations with referral traffic or commercial outcomes where attribution is available. Why Does GEO Pricing in India Vary So Widely? GEO services cost in India varies because the underlying workload changes considerably across brands. Prompt coverage, content requirements, existing authority, website complexity, market competition, and measurement depth can all increase execution needs. Agencies also differ in how much implementation they include inside the monthly fee. Consider two B2B companies paying for GEO. The first already has strong organic rankings and extensive expert content. Its main requirement may involve restructuring existing pages and improving measurement. The second may lack comparison pages, evidence-backed guides, founder expertise, and external validation. Those companies should not receive the same scope or price. Cost Driver Lower-Complexity Situation Higher-Complexity Situation Prompt portfolio Small set of priority buyer questions Large multi-product prompt library Existing content Strong library needing targeted refreshes Major informational and commercial gaps Market complexity Narrow service category Multiple services, regions, or audiences Authority position Recognized brand with external coverage Limited independent validation Website condition Strong search fundamentals Indexing or architecture problems Measurement depth Periodic manual checks Wider recurring platform analysis The same principle applies to content planning. Scribblers India’s content strategy services start by connecting assets with business priorities rather than treating publishing volume as the objective. Once these variables are clear, businesses can decide whether they require diagnosis first or an ongoing execution program. How Is GEO
Finding a reliable answer for GEO services cost in India has become difficult because agencies package very different work under the same label. One provider may offer prompt tracking and basic technical checks. Another may combine research, content development, authority building, page optimization, and ongoing visibility measurement. That difference explains why published prices can range from a few thousand rupees for basic audits to several lakh rupees monthly. Comparing those numbers without understanding their scope can therefore create a misleading view of the actual market. Businesses need a better pricing framework. The right question is not simply, “How much do GEO services cost in India?” The more useful question asks what level of GEO work your current visibility gaps require. Key Takeaways GEO retainers in India vary widely because the scope of services differs among providers. A serious GEO audit should diagnose visibility gaps before recommending monthly execution. Monthly GEO pricing rises with content depth and broader cross-platform measurement complexity. Cheap packages often cover monitoring while larger retainers fund ongoing implementation work. Google requires no special AI markup for AI Overview or Mode visibility. Brands should compare deliverables and ownership before judging the prices of competing GEO agencies. Strong SEO foundations still support generative visibility across Google AI experiences today. GEO performance requires repeatable prompts, along with source and business outcome measurement. How Much Do GEO Services Cost in India in 2026? GEO services in India can cost around ₹15,000–₹60,000 for a substantive one-time audit. Focused monthly programs often start near ₹35,000–₹80,000. Broader growth retainers may reach ₹75,000–₹1.5 lakh, while scaled programs can exceed ₹1.5–₹3.5 lakh monthly. These ranges for GEO services cost in India should be treated as planning benchmarks rather than fixed industry prices. Publicly listed Indian offers currently show monthly pricing starting around ₹18,000, ₹35,000, and ₹40,000 across different providers. Other published GEO pricing frameworks set higher retainers at ₹1.5 lakh per month or above. The table below normalizes those public offers by the likely depth of engagement. Engagement Type Indicative 2026 Budget Typical Scope Suitable For Focused GEO audit ₹15,000–₹60,000 one-time Visibility baseline, prompt testing, competitor review, prioritized roadmap First-time GEO buyers Focused retainer ₹35,000–₹80,000 monthly Priority prompts, key-page updates, basic tracking, limited new content Smaller brands Growth program ₹75,000–₹1.5 lakh monthly Content creation, refreshes, competitor tracking, deeper source analysis Growing B2B brands Scaled GEO program ₹1.5–₹3.5 lakh+ monthly Larger topic coverage, authority assets, cross-platform measurement, deeper execution Competitive categories Enterprise engagement ₹3 lakh+ monthly Multiple markets, complex portfolios, extensive authority work, dedicated reporting Larger organizations UpGrowth, for example, places Indian mid-market GEO and AEO retainers at ₹75,000 to ₹3.5 lakh per month. Other providers publish lower starting rates because their entry packages cover narrower workloads. This range makes one point clear. Price begins making sense only after you understand exactly what the agency intends to deliver. What Does GEO Services Cost in India Cover? GEO agency pricing should fund work that changes how your brand is understood and represented across generative discovery. That normally includes diagnosis and execution. A useful engagement should not be limited to improving the owned content and external information sources that influence important buyer questions. Understanding this distinction becomes easier after reviewing what generative engine optimization services involve. GEO examines buyer prompts, competing brands, relevant sources, content gaps, entity accuracy, and measurable representation across selected platforms. A robust GEO engagement in India generally covers several connected workstreams: Buyer Prompt Research: Commercially relevant prompts should reflect how buyers research problems and evaluate providers. The agency should separate high-value questions from broad informational queries. This keeps tracking connected with actual business priorities rather than producing an impressive prompt count with limited commercial value. Visibility Baseline: Initial testing should document where the brand appears across agreed AI experiences. It should also record competitor presence, citations where available, and answer context. These observations create the controlled baseline needed for later comparisons after content or authority improvements. Content Gap Mapping: Existing pages should be reviewed against the questions AI systems and buyers need answered. Scribblers India explains this process further in its AI content gap analysis framework, which identifies missing answers, weak evidence, and incomplete content coverage. Content Execution: GEO programs often require existing pages to be refreshed or new assets created. The scope may include comparison pages, expert guides, original research, case-led resources, service content, or commercially focused articles designed around verified information gaps. Measurement Cycles: Priority prompts must be tested again under comparable conditions after implementation. A useful report should show changes in brand representation and competitor presence. It should also connect those observations with referral traffic or commercial outcomes where attribution is available. Why Does GEO Pricing in India Vary So Widely? GEO services cost in India varies because the underlying workload changes considerably across brands. Prompt coverage, content requirements, existing authority, website complexity, market competition, and measurement depth can all increase execution needs. Agencies also differ in how much implementation they include inside the monthly fee. Consider two B2B companies paying for GEO. The first already has strong organic rankings and extensive expert content. Its main requirement may involve restructuring existing pages and improving measurement. The second may lack comparison pages, evidence-backed guides, founder expertise, and external validation. Those companies should not receive the same scope or price. Cost Driver Lower-Complexity Situation Higher-Complexity Situation Prompt portfolio Small set of priority buyer questions Large multi-product prompt library Existing content Strong library needing targeted refreshes Major informational and commercial gaps Market complexity Narrow service category Multiple services, regions, or audiences Authority position Recognized brand with external coverage Limited independent validation Website condition Strong search fundamentals Indexing or architecture problems Measurement depth Periodic manual checks Wider recurring platform analysis The same principle applies to content planning. Scribblers India’s content strategy services start by connecting assets with business priorities rather than treating publishing volume as the objective. Once these variables are clear, businesses can decide whether they require diagnosis first or an ongoing execution program. How Is GEO
What Should Businesses Expect From a GEO Agency Retainer in 2026?
A GEO retainer can describe very different agency engagements. One proposal may combine prompt tracking, page refreshes, technical reviews, content development, external-source analysis, and recurring measurement. Another may provide a monthly dashboard with limited explanation of what the team will change once new findings emerge. That difference matters as AI-assisted discovery becomes a larger part of search behavior. Google says AI Overviews now reach more than 2.5 billion monthly active users, while AI Mode has surpassed one billion. These search experiences create new discovery opportunities while making measurement more complex. A useful engagement should therefore connect diagnosis with execution and repeat measurement. This guide explains what businesses should receive during the first 90 days, which services fall within the ongoing scope, how reporting and SLAs should work, and when a recurring arrangement warrants continued investment. Key Takeaways GEO retainers should establish measurable visibility before recommending large content changes. Early work should identify priority gaps before expanding monthly publishing volume. Core prompt sets make visibility changes easier to compare across reporting periods. Monthly reports should connect observed movement with specific implementation decisions and owners. Agencies should guarantee controllable work rather than citations or recommendation positions. Retainer costs change with markets, prompts, content needs, and implementation depth. Monthly priorities should evolve when evidence reveals stronger or weaker opportunities. What Is a GEO Retainer? A GEO retainer is an ongoing engagement focused on improving and measuring how a brand appears across AI-assisted discovery. The work can include prompt monitoring, content updates, technical checks, source analysis, authority development, and reporting, with priorities changing as new evidence emerges. The important distinction is recurrence. AI-generated answers can change as public information, competing content, platform behavior, and buyer questions evolve. A recurring engagement gives the team a structured way to observe those changes, implement improvements, and test whether the resulting AI visibility pattern changes afterward. That does not mean every company needs monthly support. Some businesses need a baseline first, while others already know which pages or information gaps require attention. The engagement model should therefore follow the problem’s maturity rather than immediately default to a retainer. Engagement Model Primary Purpose Best Fit GEO Audit Diagnose current visibility and information gaps Brands without a reliable baseline Fixed Sprint Address a defined group of priorities Teams with known implementation needs Ongoing Engagement Measure and improve recurring visibility Brands with sustained AI-search opportunity Internal Program Build and manage capability in-house Mature teams with adequate expertise Teams that are still assessing overall readiness can use Scribblers India’s AI Search Visibility Scorecard to identify broad weaknesses before deciding whether deeper diagnosis or recurring implementation is justified. The next question is whether the visibility environment changes enough to warrant continuing work. Why Does GEO Require Ongoing Work in 2026? Ongoing GEO work is useful because AI search visibility can change over time. A brand may appear for one prompt and disappear for another, while cited sources and recommendation context can also shift. Repeated testing helps businesses identify consistent patterns instead of reacting to individual responses. The wider environment is changing quickly too. After a May 2026 update to the ChatGPT interface that made brand links more prominent, total referral traffic increased by 157.7% week over week. Changes like this can quickly affect how users discover and visit brands through AI platforms. A recurring GEO program should therefore monitor both the information a brand controls and changes happening outside its website. Content quality, factual accuracy, technical access, and published evidence can be improved directly, while competitor activity, platform updates, cited sources, and evolving buyer questions require ongoing monitoring. What Services Should a GEO Services Retainer Include? A GEO retainer should connect measurement with practical improvements across priority content and supporting public evidence. The exact mix should follow the baseline findings. Strong programs avoid treating monthly content volume as the objective when existing pages or source gaps create the larger visibility problem. 1. Commercial Prompt Mapping and AI Visibility Monitoring Prompt Mapping defines the category, recommendation, comparison, alternative, and validation questions to monitor. Each prompt should have a clear business reason for inclusion, while the baseline should record brand appearances, relevant competitors, description accuracy, and cited sources using consistent testing rules. 2. Prompt-to-Page Content Mapping Content Mapping connects commercially important questions with the strongest existing destination pages. Some prompts reveal missing assets, while others expose incomplete service pages or comparisons. Scribblers India’s AI content gap analysis explains why many visibility gaps can be solved by strengthening existing pages rather than adding another URL. 3. Technical Search and Crawler Review Technical Review checks whether priority information remains accessible to relevant search systems. Google says existing SEO fundamentals remain relevant for AI Overviews and AI Mode, with no special AI-specific technical requirements. OpenAI separately recommends allowing OAI-SearchBot when publishers want their public content to be discoverable in ChatGPT Search. 4. Priority Page Refreshes Page Refreshes improve existing commercial assets when they already serve the right search job. Updates can strengthen direct answers, product or service detail, comparison depth, evidence, freshness, internal pathways, and factual consistency without creating unnecessary content overlap across the site. 5. New Authority Assets Authority Assets become useful when no existing page can answer an important question properly. These may include research reports, buyer guides, comparison resources, case studies, glossaries, or expert-led thought leadership that provides buyers with deeper evidence on a category or decision. 6. External Source and Brand Evidence Review Source Review examines how credible third-party pages describe the company and its expertise. Relevant publications, review platforms, partner profiles, directories, customer evidence, or expert pages can reveal inconsistencies that website-only analysis misses and may influence how buyers validate AI-generated recommendations. 7. Measurement and Monthly Reprioritization Recurring Measurement repeats the stable prompt panel and connects observed movement with the next implementation cycle. Scribblers India’s GEO services apply the same connected approach, linking search foundations, answer-led content, authority development, and visibility measurement to documented business gaps. What Should Happen During GEO Onboarding? GEO onboarding should establish business
A GEO retainer can describe very different agency engagements. One proposal may combine prompt tracking, page refreshes, technical reviews, content development, external-source analysis, and recurring measurement. Another may provide a monthly dashboard with limited explanation of what the team will change once new findings emerge. That difference matters as AI-assisted discovery becomes a larger part of search behavior. Google says AI Overviews now reach more than 2.5 billion monthly active users, while AI Mode has surpassed one billion. These search experiences create new discovery opportunities while making measurement more complex. A useful engagement should therefore connect diagnosis with execution and repeat measurement. This guide explains what businesses should receive during the first 90 days, which services fall within the ongoing scope, how reporting and SLAs should work, and when a recurring arrangement warrants continued investment. Key Takeaways GEO retainers should establish measurable visibility before recommending large content changes. Early work should identify priority gaps before expanding monthly publishing volume. Core prompt sets make visibility changes easier to compare across reporting periods. Monthly reports should connect observed movement with specific implementation decisions and owners. Agencies should guarantee controllable work rather than citations or recommendation positions. Retainer costs change with markets, prompts, content needs, and implementation depth. Monthly priorities should evolve when evidence reveals stronger or weaker opportunities. What Is a GEO Retainer? A GEO retainer is an ongoing engagement focused on improving and measuring how a brand appears across AI-assisted discovery. The work can include prompt monitoring, content updates, technical checks, source analysis, authority development, and reporting, with priorities changing as new evidence emerges. The important distinction is recurrence. AI-generated answers can change as public information, competing content, platform behavior, and buyer questions evolve. A recurring engagement gives the team a structured way to observe those changes, implement improvements, and test whether the resulting AI visibility pattern changes afterward. That does not mean every company needs monthly support. Some businesses need a baseline first, while others already know which pages or information gaps require attention. The engagement model should therefore follow the problem’s maturity rather than immediately default to a retainer. Engagement Model Primary Purpose Best Fit GEO Audit Diagnose current visibility and information gaps Brands without a reliable baseline Fixed Sprint Address a defined group of priorities Teams with known implementation needs Ongoing Engagement Measure and improve recurring visibility Brands with sustained AI-search opportunity Internal Program Build and manage capability in-house Mature teams with adequate expertise Teams that are still assessing overall readiness can use Scribblers India’s AI Search Visibility Scorecard to identify broad weaknesses before deciding whether deeper diagnosis or recurring implementation is justified. The next question is whether the visibility environment changes enough to warrant continuing work. Why Does GEO Require Ongoing Work in 2026? Ongoing GEO work is useful because AI search visibility can change over time. A brand may appear for one prompt and disappear for another, while cited sources and recommendation context can also shift. Repeated testing helps businesses identify consistent patterns instead of reacting to individual responses. The wider environment is changing quickly too. After a May 2026 update to the ChatGPT interface that made brand links more prominent, total referral traffic increased by 157.7% week over week. Changes like this can quickly affect how users discover and visit brands through AI platforms. A recurring GEO program should therefore monitor both the information a brand controls and changes happening outside its website. Content quality, factual accuracy, technical access, and published evidence can be improved directly, while competitor activity, platform updates, cited sources, and evolving buyer questions require ongoing monitoring. What Services Should a GEO Services Retainer Include? A GEO retainer should connect measurement with practical improvements across priority content and supporting public evidence. The exact mix should follow the baseline findings. Strong programs avoid treating monthly content volume as the objective when existing pages or source gaps create the larger visibility problem. 1. Commercial Prompt Mapping and AI Visibility Monitoring Prompt Mapping defines the category, recommendation, comparison, alternative, and validation questions to monitor. Each prompt should have a clear business reason for inclusion, while the baseline should record brand appearances, relevant competitors, description accuracy, and cited sources using consistent testing rules. 2. Prompt-to-Page Content Mapping Content Mapping connects commercially important questions with the strongest existing destination pages. Some prompts reveal missing assets, while others expose incomplete service pages or comparisons. Scribblers India’s AI content gap analysis explains why many visibility gaps can be solved by strengthening existing pages rather than adding another URL. 3. Technical Search and Crawler Review Technical Review checks whether priority information remains accessible to relevant search systems. Google says existing SEO fundamentals remain relevant for AI Overviews and AI Mode, with no special AI-specific technical requirements. OpenAI separately recommends allowing OAI-SearchBot when publishers want their public content to be discoverable in ChatGPT Search. 4. Priority Page Refreshes Page Refreshes improve existing commercial assets when they already serve the right search job. Updates can strengthen direct answers, product or service detail, comparison depth, evidence, freshness, internal pathways, and factual consistency without creating unnecessary content overlap across the site. 5. New Authority Assets Authority Assets become useful when no existing page can answer an important question properly. These may include research reports, buyer guides, comparison resources, case studies, glossaries, or expert-led thought leadership that provides buyers with deeper evidence on a category or decision. 6. External Source and Brand Evidence Review Source Review examines how credible third-party pages describe the company and its expertise. Relevant publications, review platforms, partner profiles, directories, customer evidence, or expert pages can reveal inconsistencies that website-only analysis misses and may influence how buyers validate AI-generated recommendations. 7. Measurement and Monthly Reprioritization Recurring Measurement repeats the stable prompt panel and connects observed movement with the next implementation cycle. Scribblers India’s GEO services apply the same connected approach, linking search foundations, answer-led content, authority development, and visibility measurement to documented business gaps. What Should Happen During GEO Onboarding? GEO onboarding should establish business